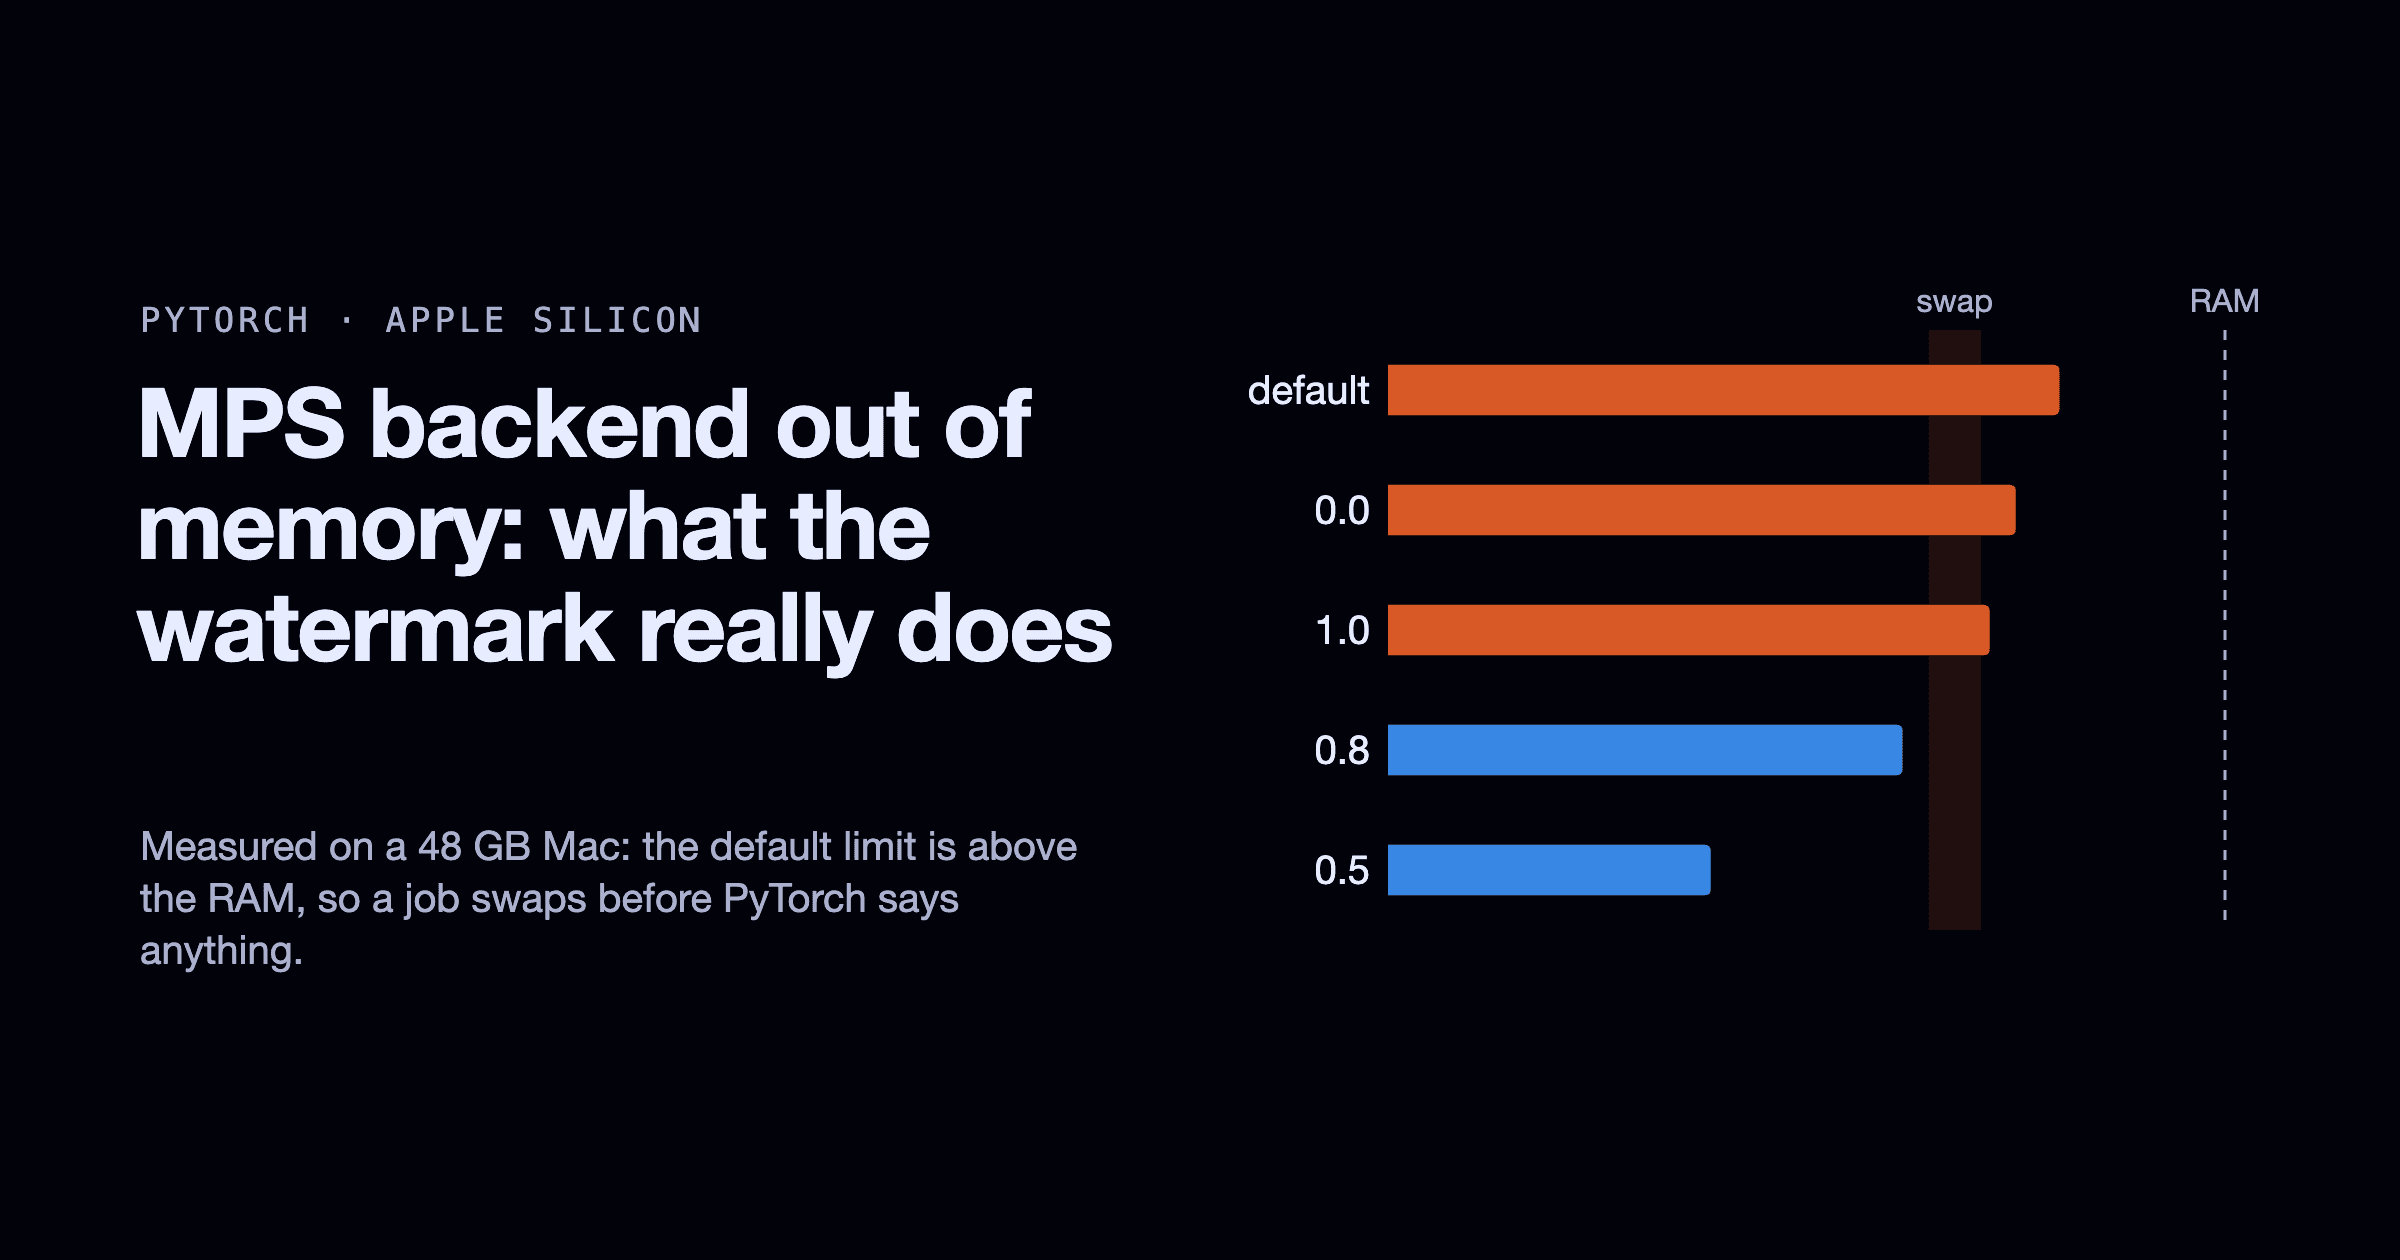
MPS backend out of memory on a Mac: what the numbers mean and how to set the watermark
On a 48 GB Mac the default MPS limit is higher than the RAM, so a big PyTorch job swaps before it ever raises this error. Measured: what the default, 0.0, 1.0, 0.8 and 0.5 do, and why the low ratio has to be set too.
Read the note →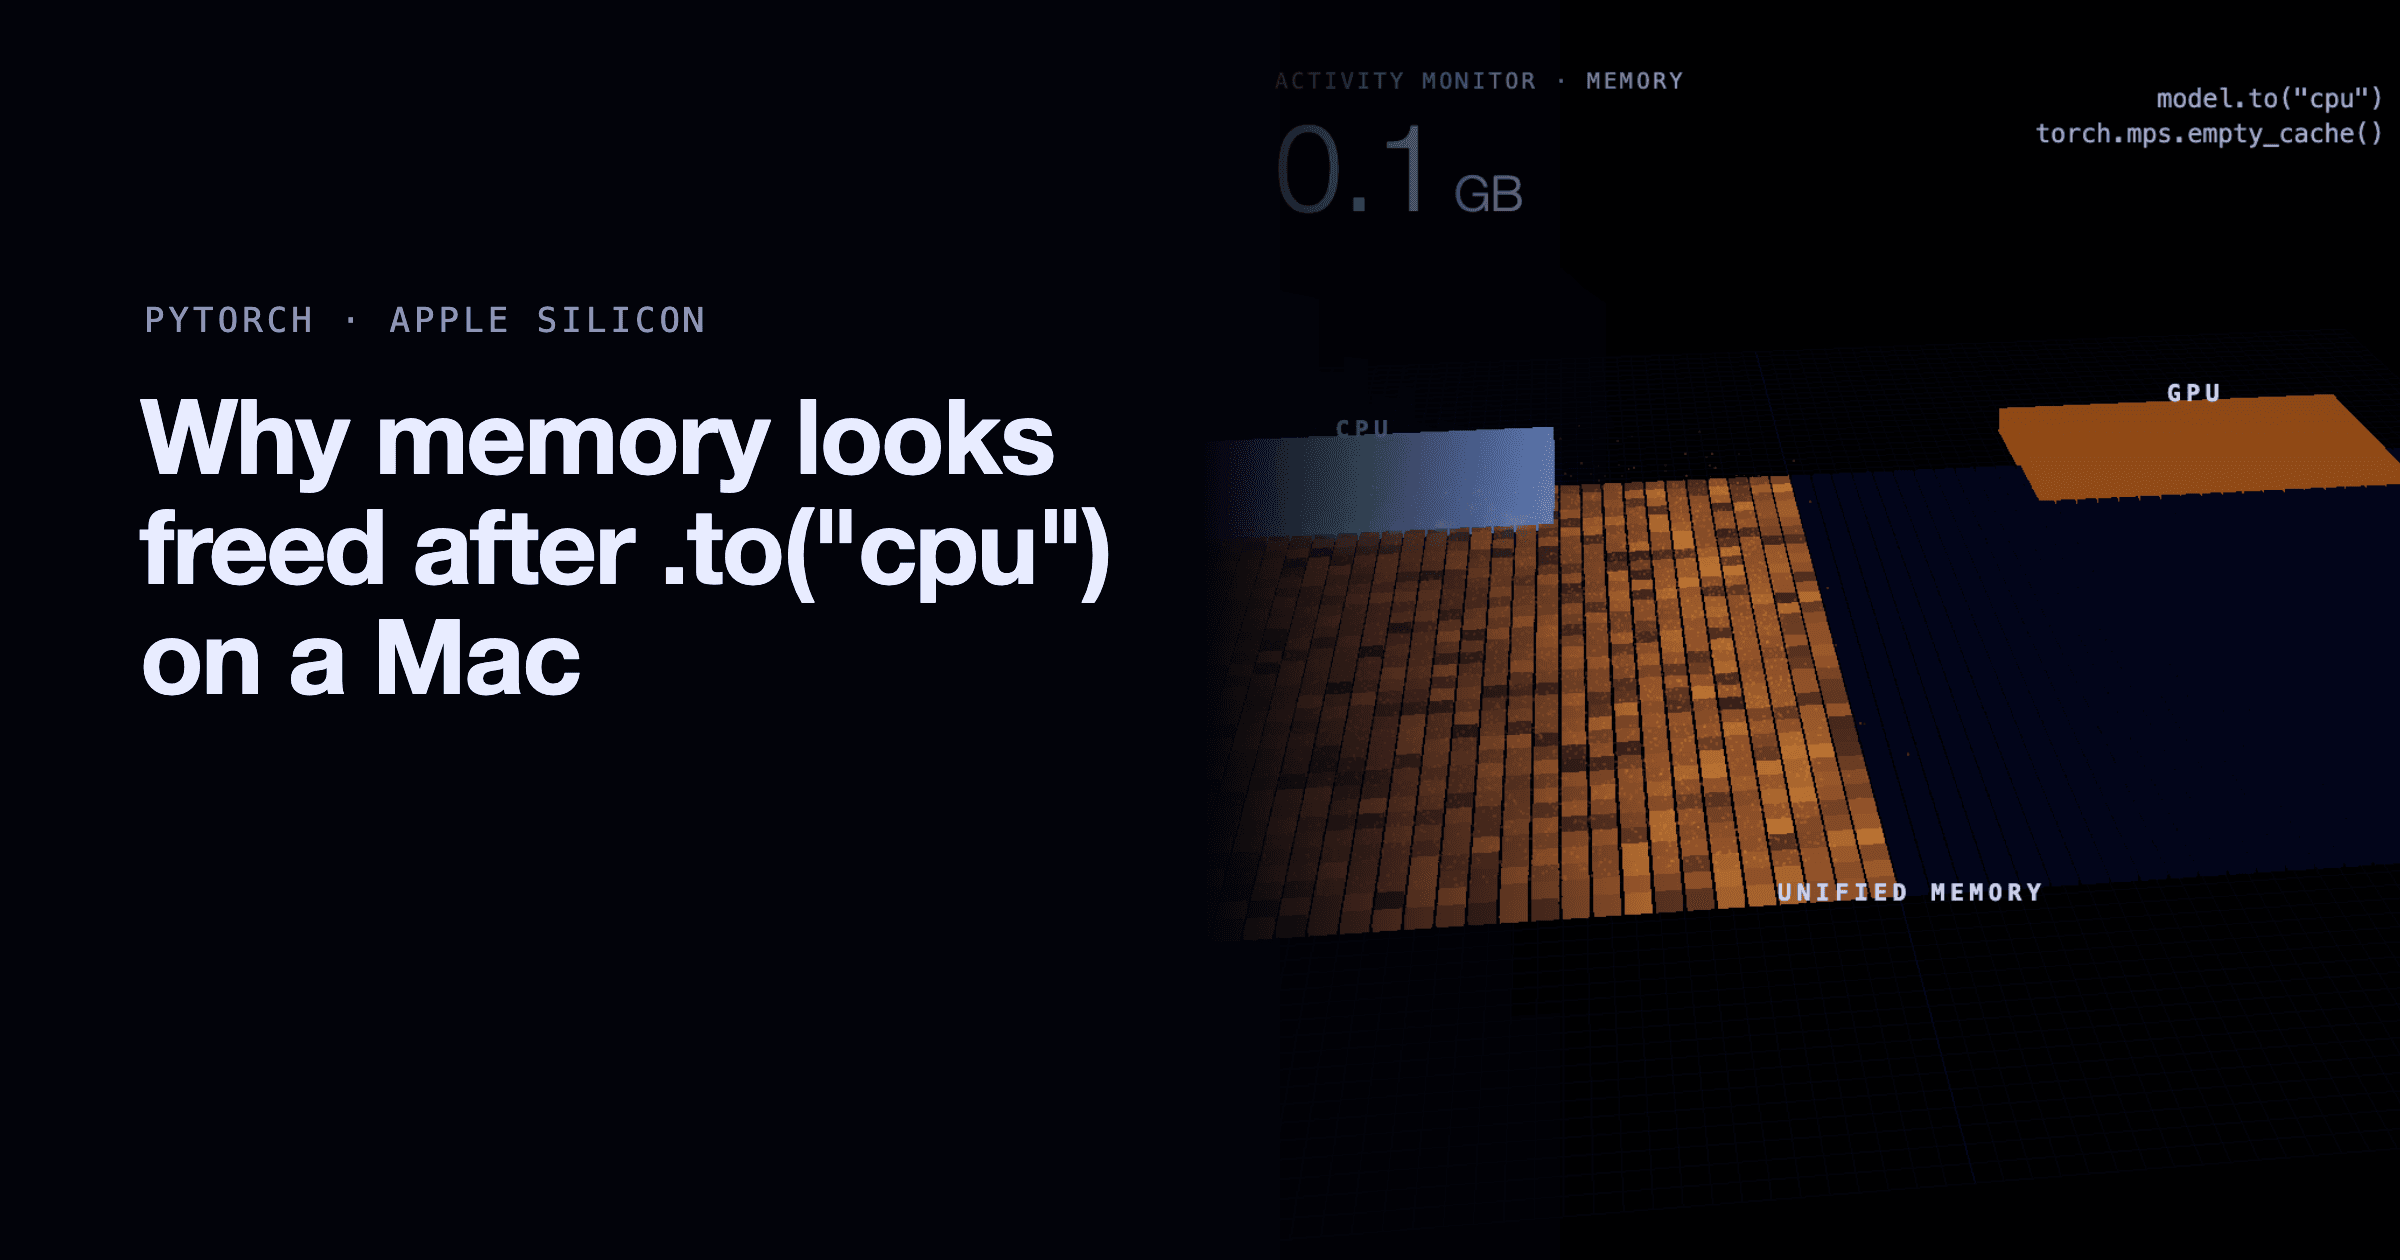
PyTorch on a Mac: why memory looks freed after .to("cpu")
On Apple Silicon, moving a tensor from mps to the CPU drops the process footprint to almost zero, yet the copy still takes the same memory. A 4 GiB example, what it means for model CPU offload, and how to check a run.
Read the note →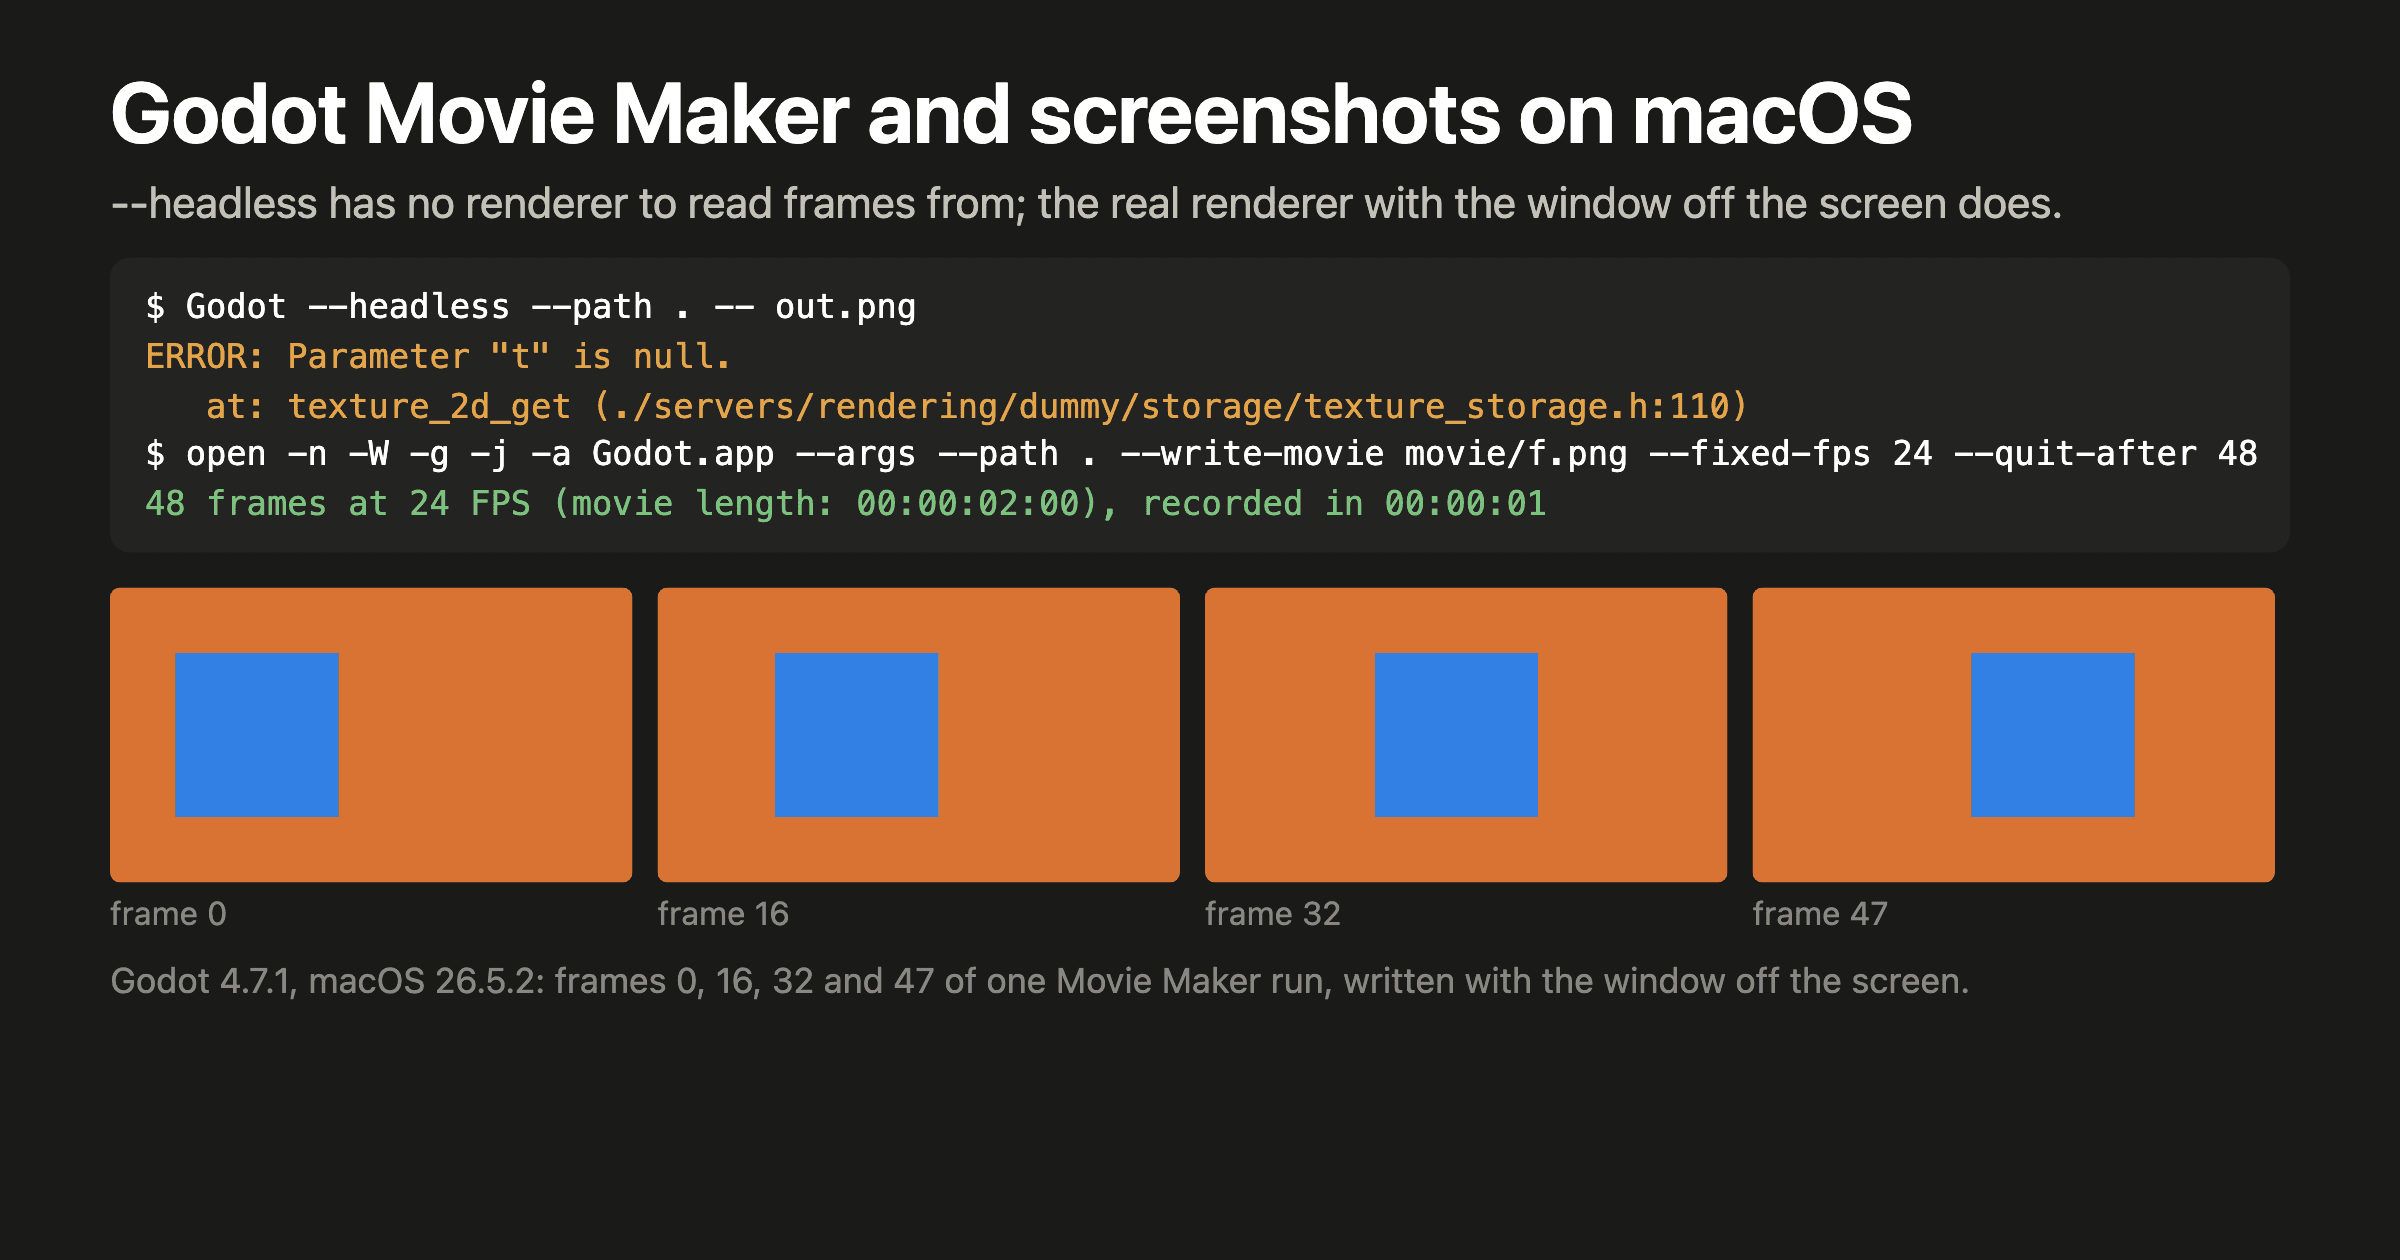
Godot Movie Maker and screenshots on macOS without --headless
On macOS, Godot's --headless mode has no renderer to read frames from. A real renderer with the window off the screen captures screenshots and Movie Maker videos; focus is the part I haven't solved.
Read the note →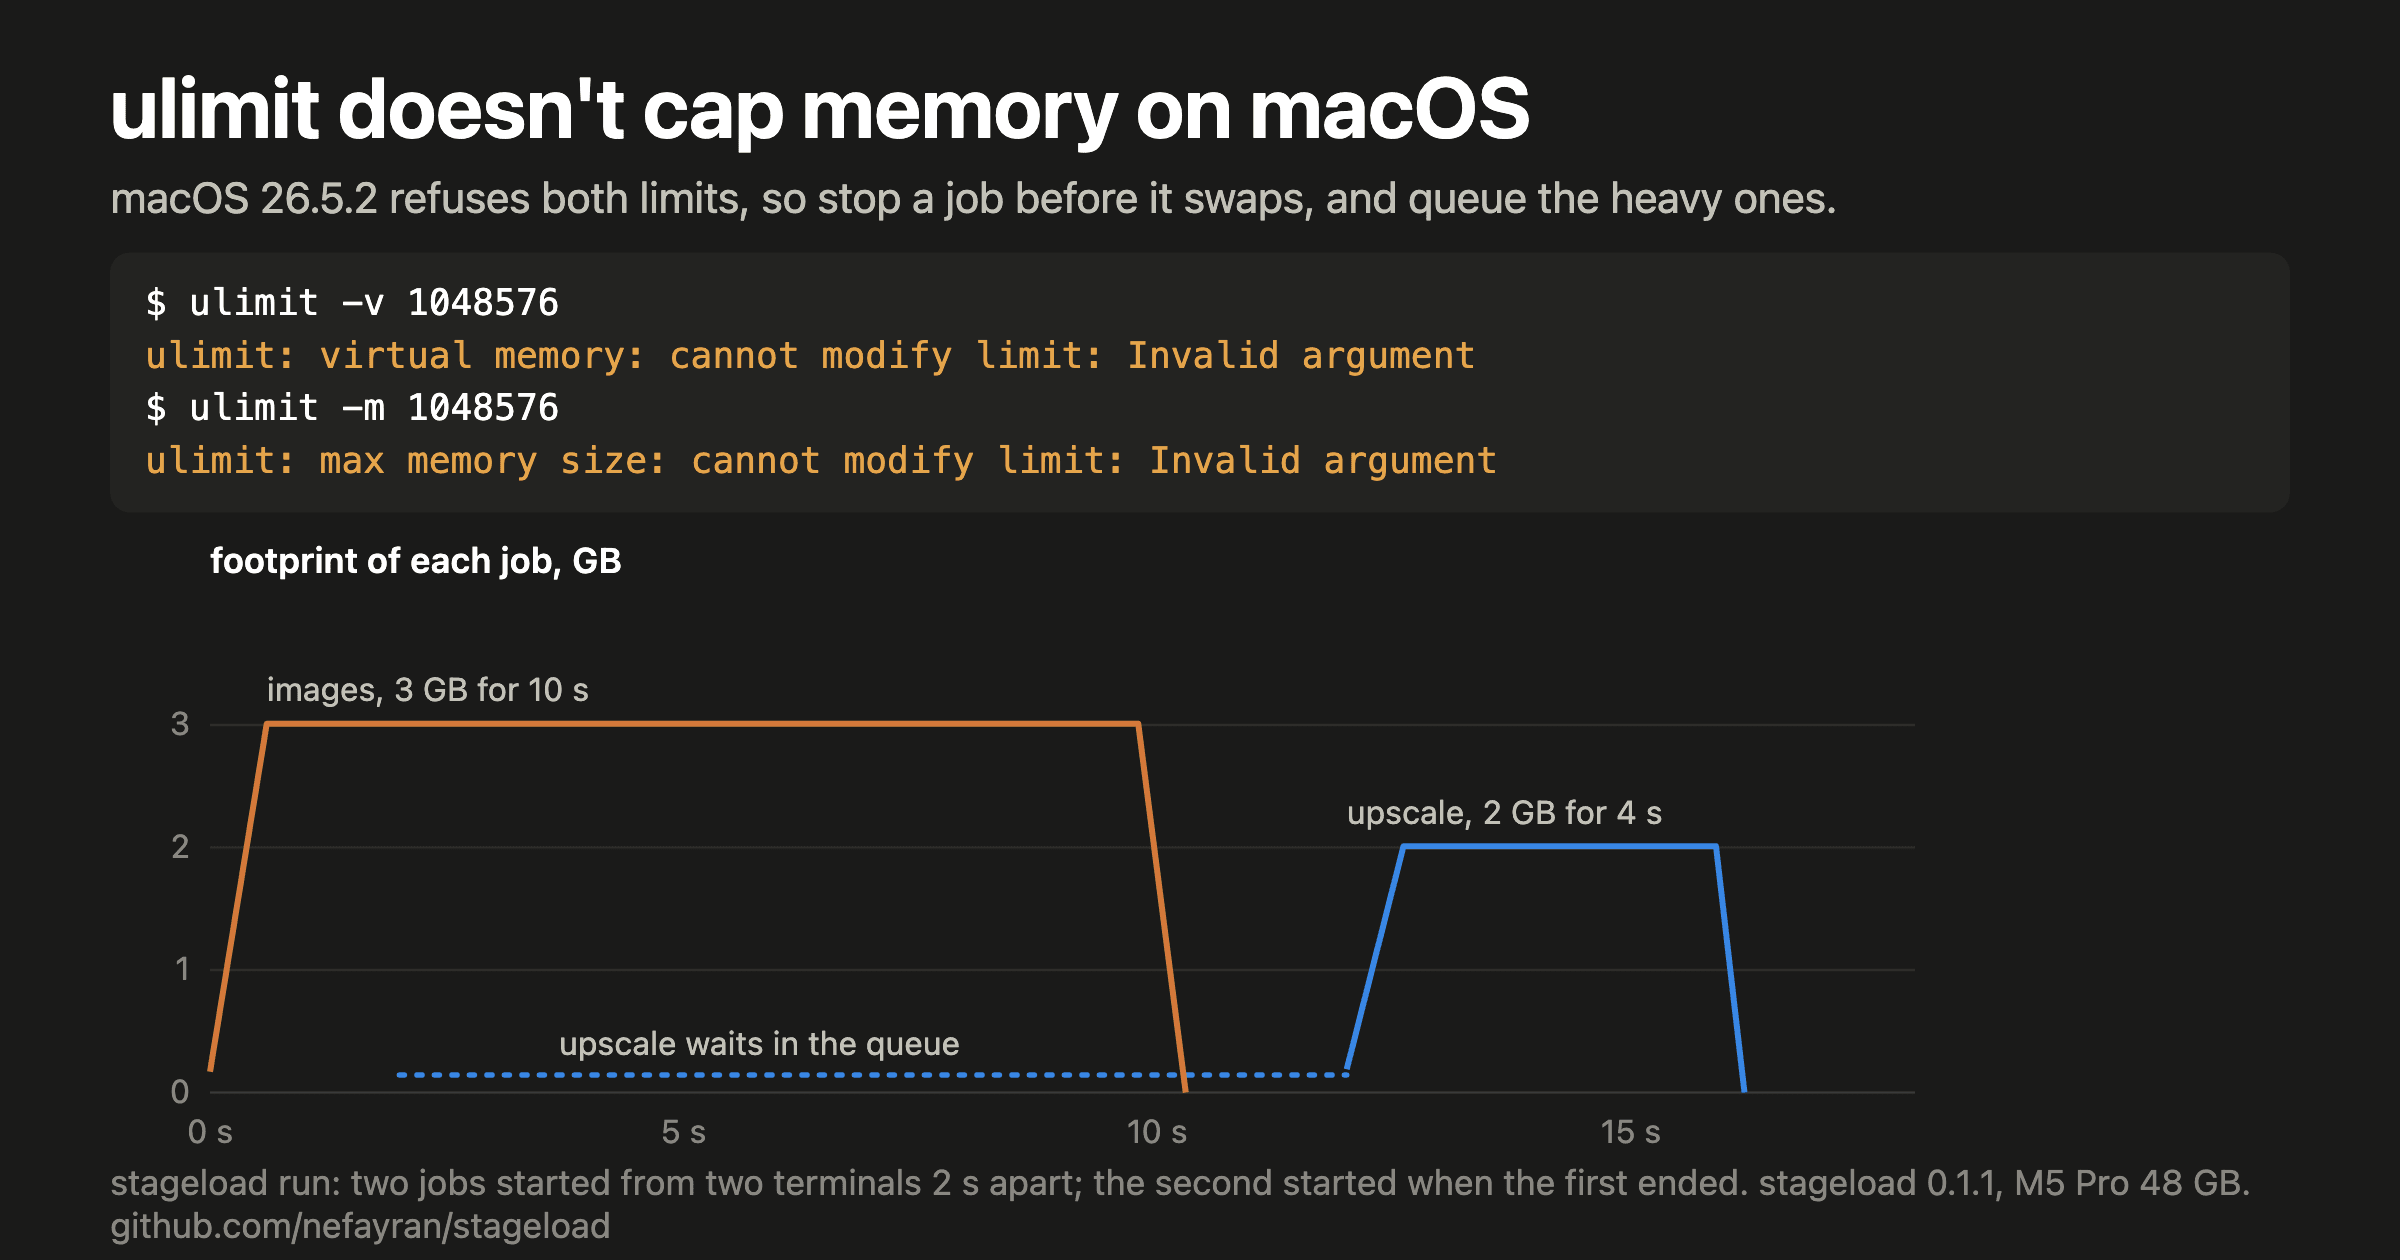
ulimit doesn't cap memory on macOS: stop a job before it swaps
On macOS, ulimit -v and ulimit -m fail with Invalid argument, so a Python job can take all the memory and push the Mac into swap. Watching swap and queuing heavy jobs works instead.
Read the note →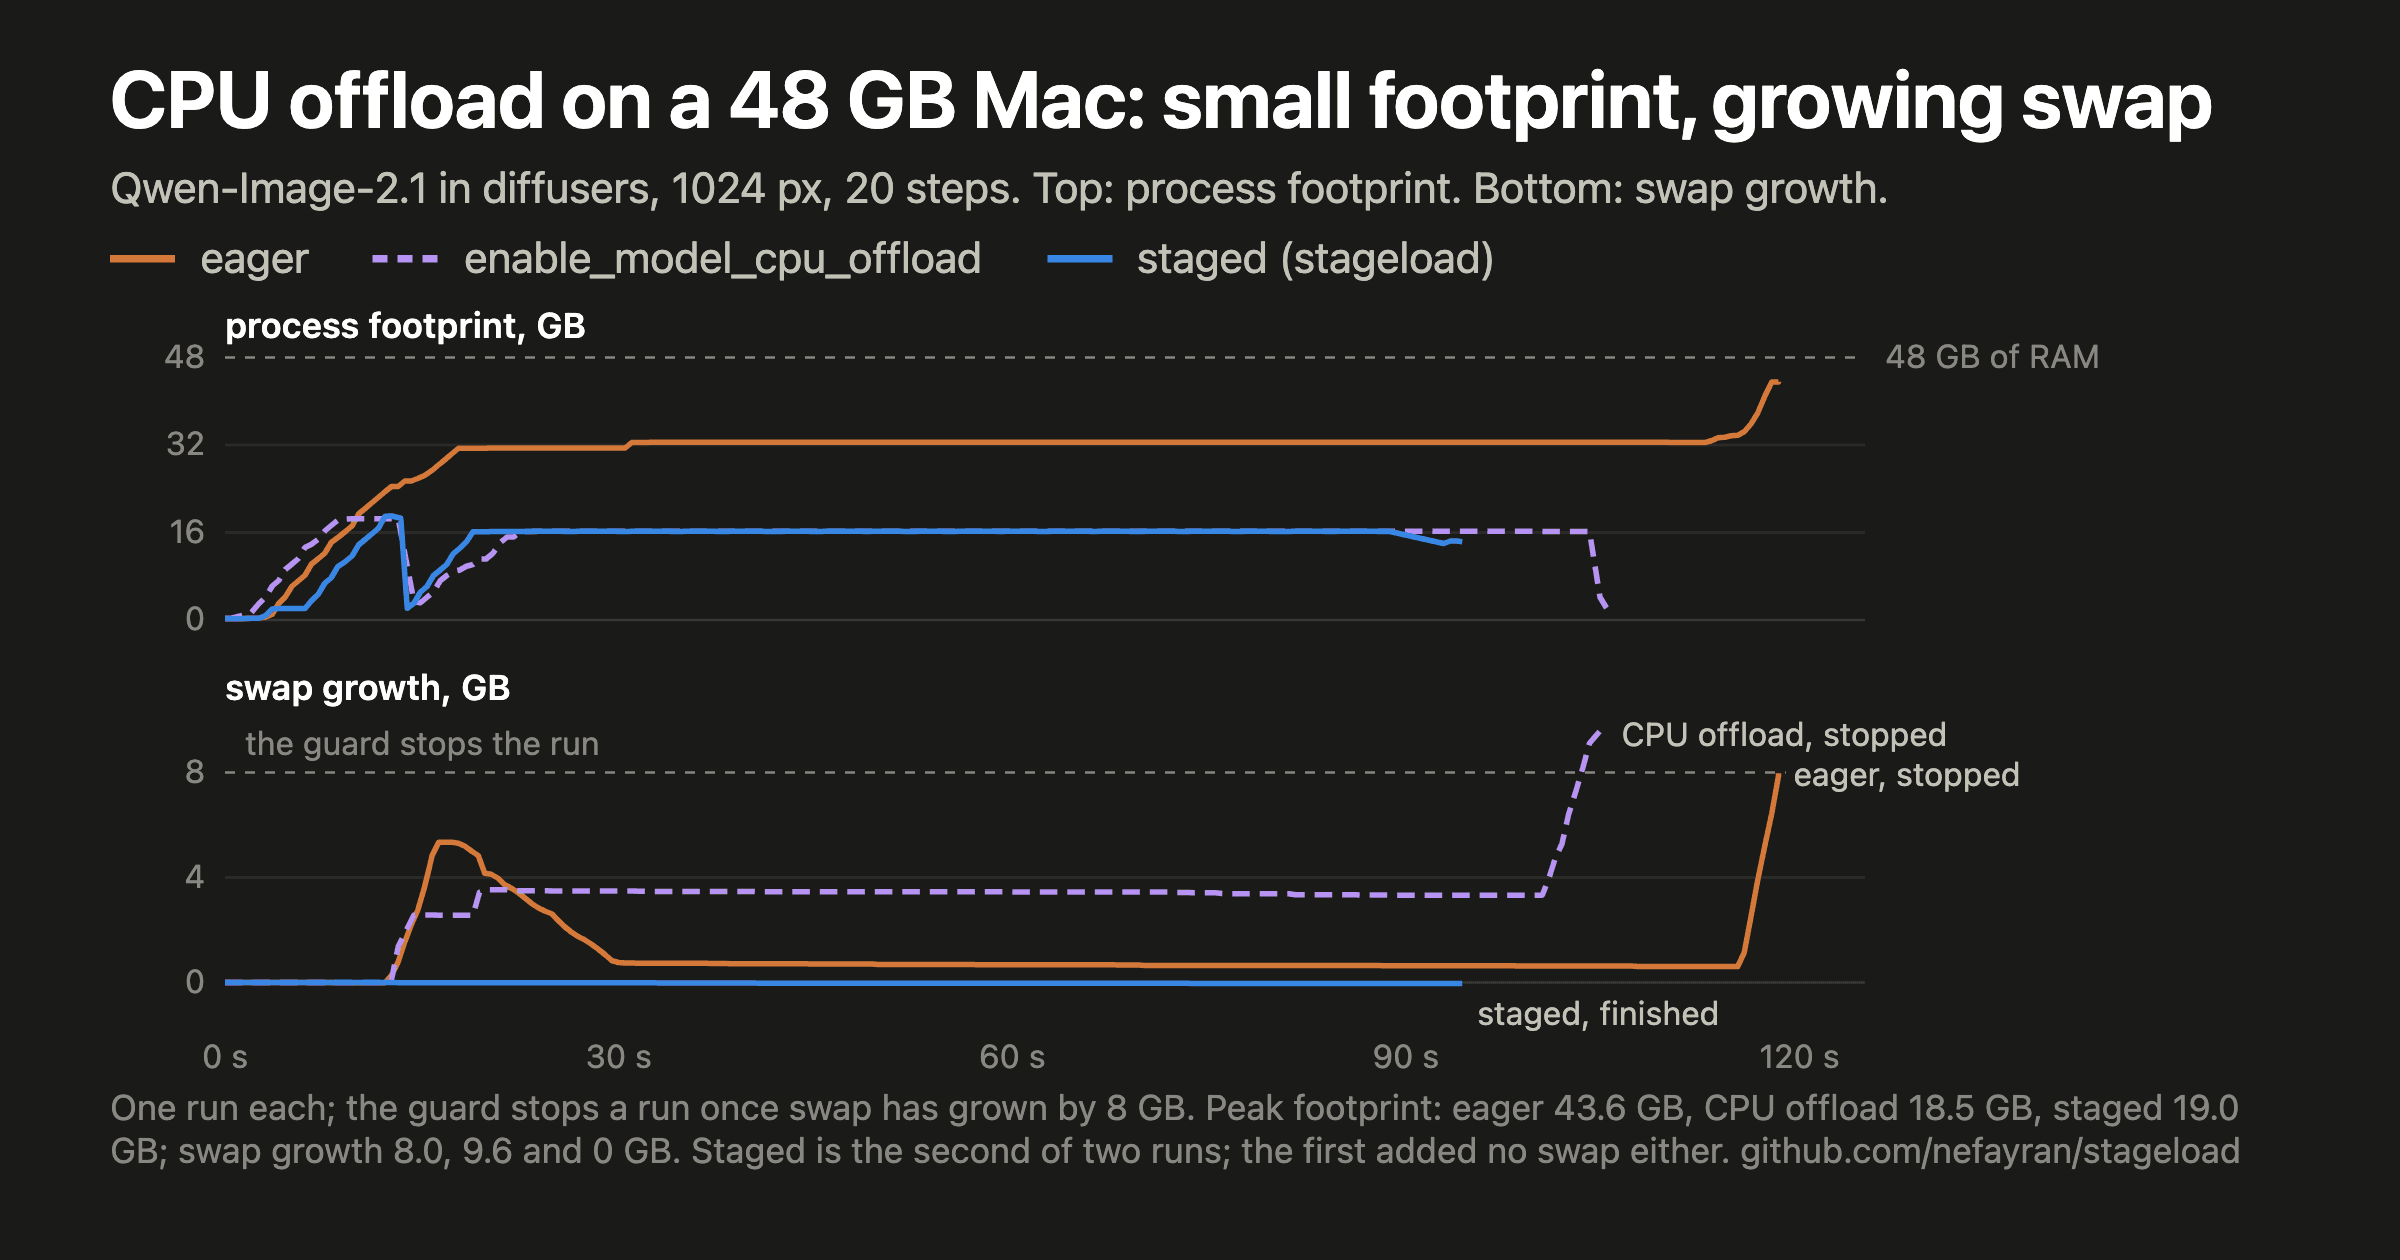
Model CPU offload on a 48 GB Mac: 18.5 GB footprint and 9.6 GB of swap
With diffusers' enable_model_cpu_offload, Qwen-Image-2.1 on a 48 GB Mac kept its process footprint at 18.5 GB, but swap grew by 9.6 GB and the memory guard stopped it in the VAE decode. Staged loading peaked at 19.0 GB and added no swap.
Read the note →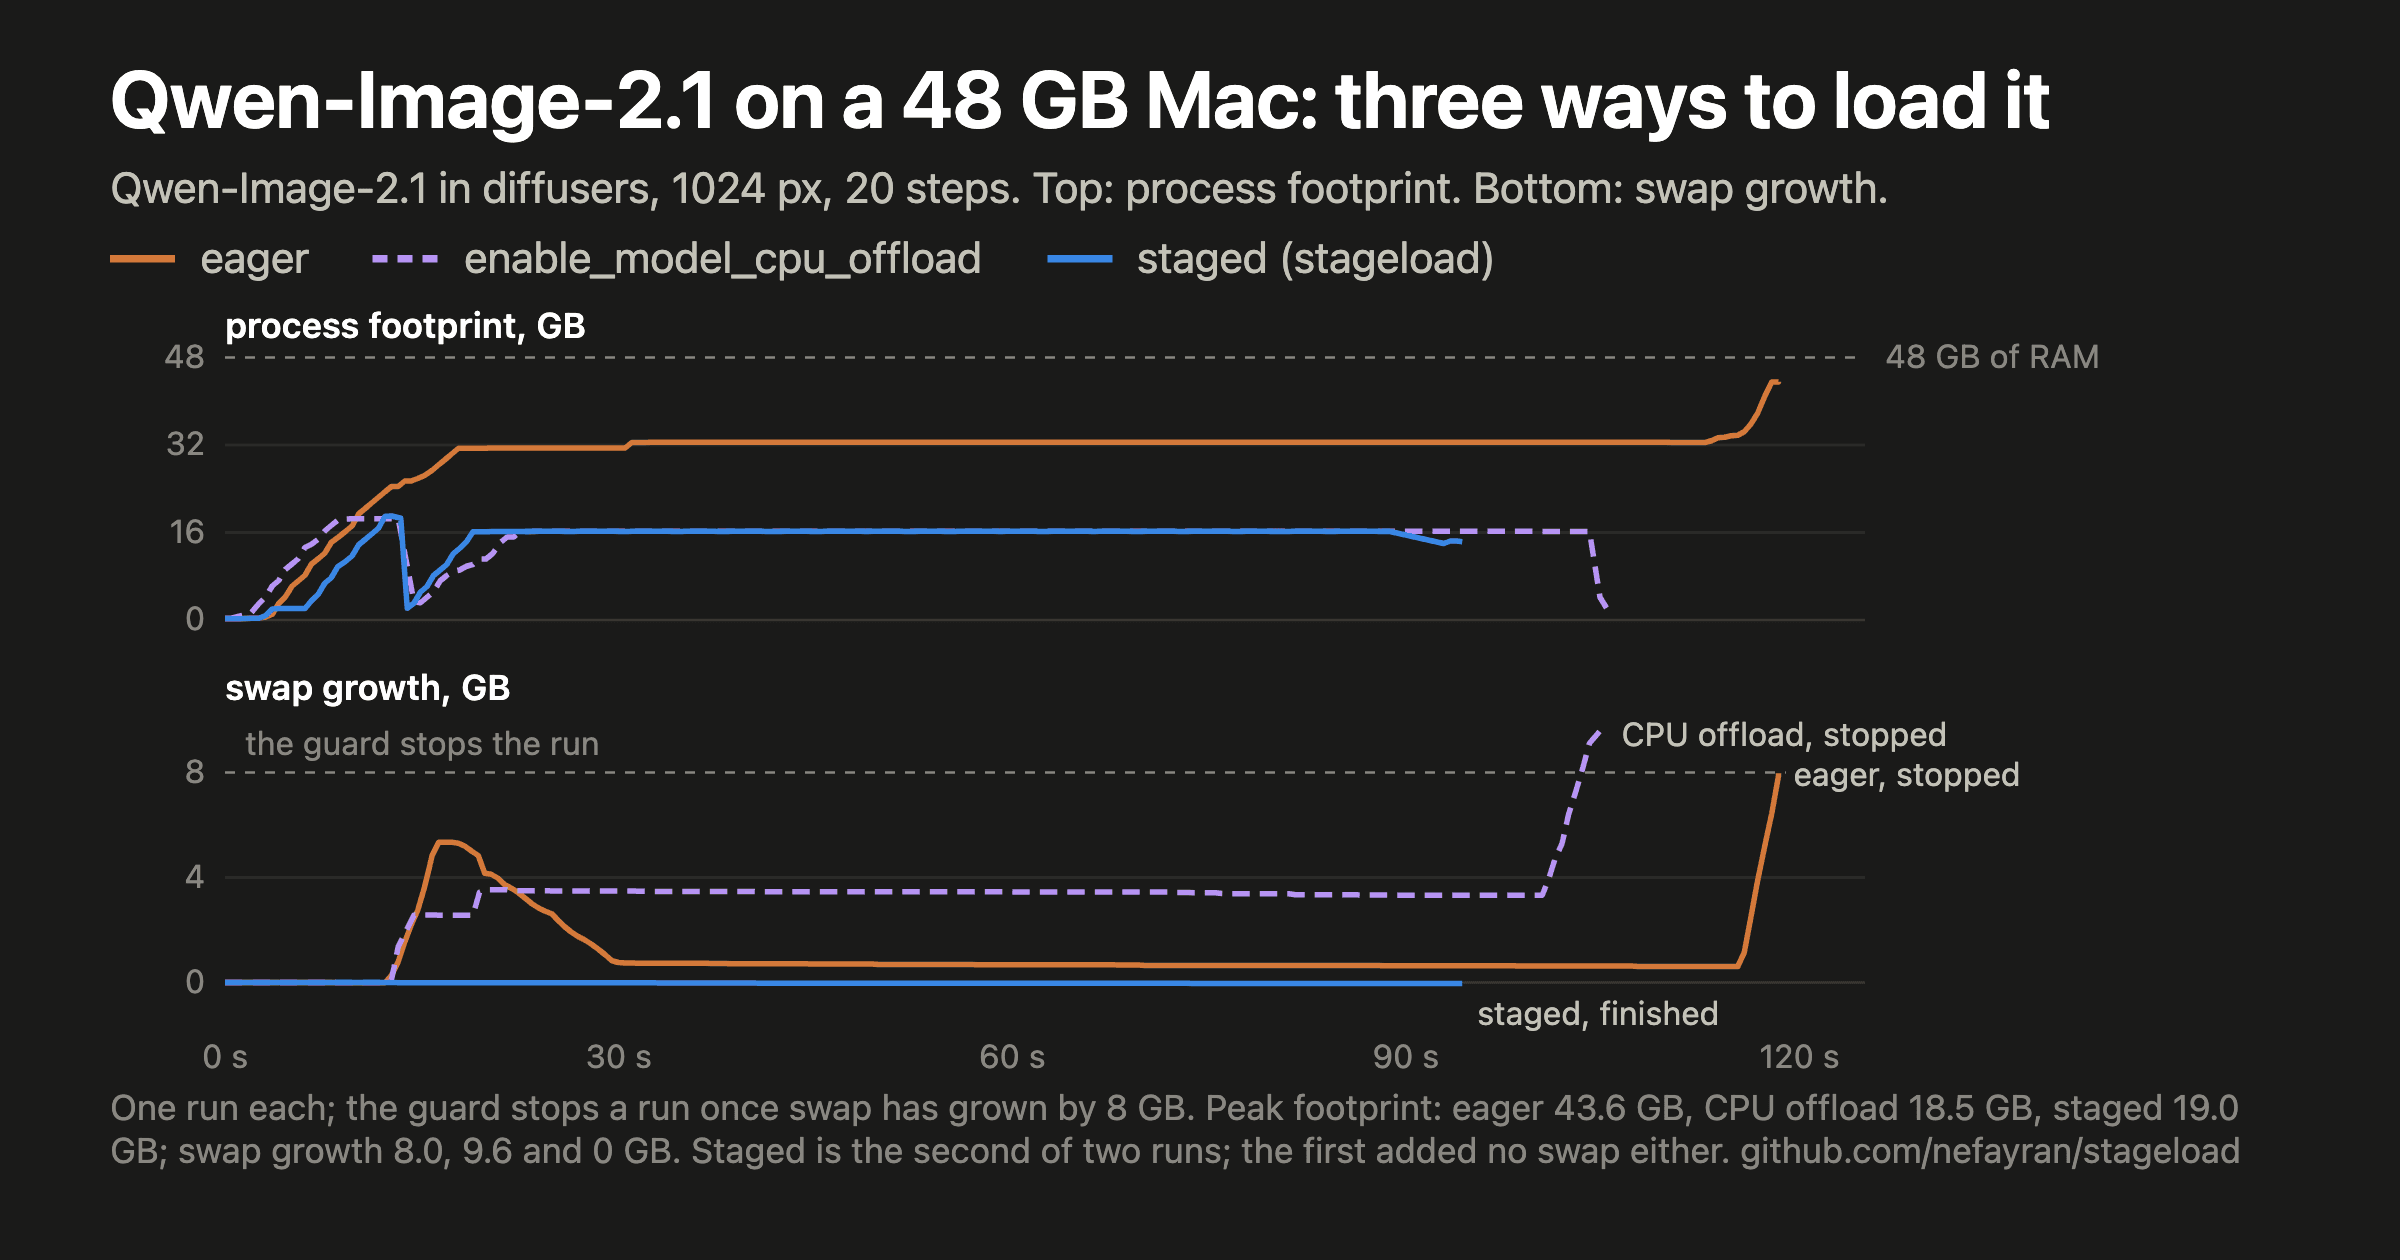
How to run Qwen-Image-2.1 on a 48 GB Mac without swap
In diffusers, Qwen-Image-2.1 takes 31.4 GB once loaded, and its VAE decode took it 11 GB higher on a 48 GB Mac. Eager loading and model CPU offload both went into swap; loading one model per stage peaked at 19.0 GB with no swap. Code and numbers.
Read the note →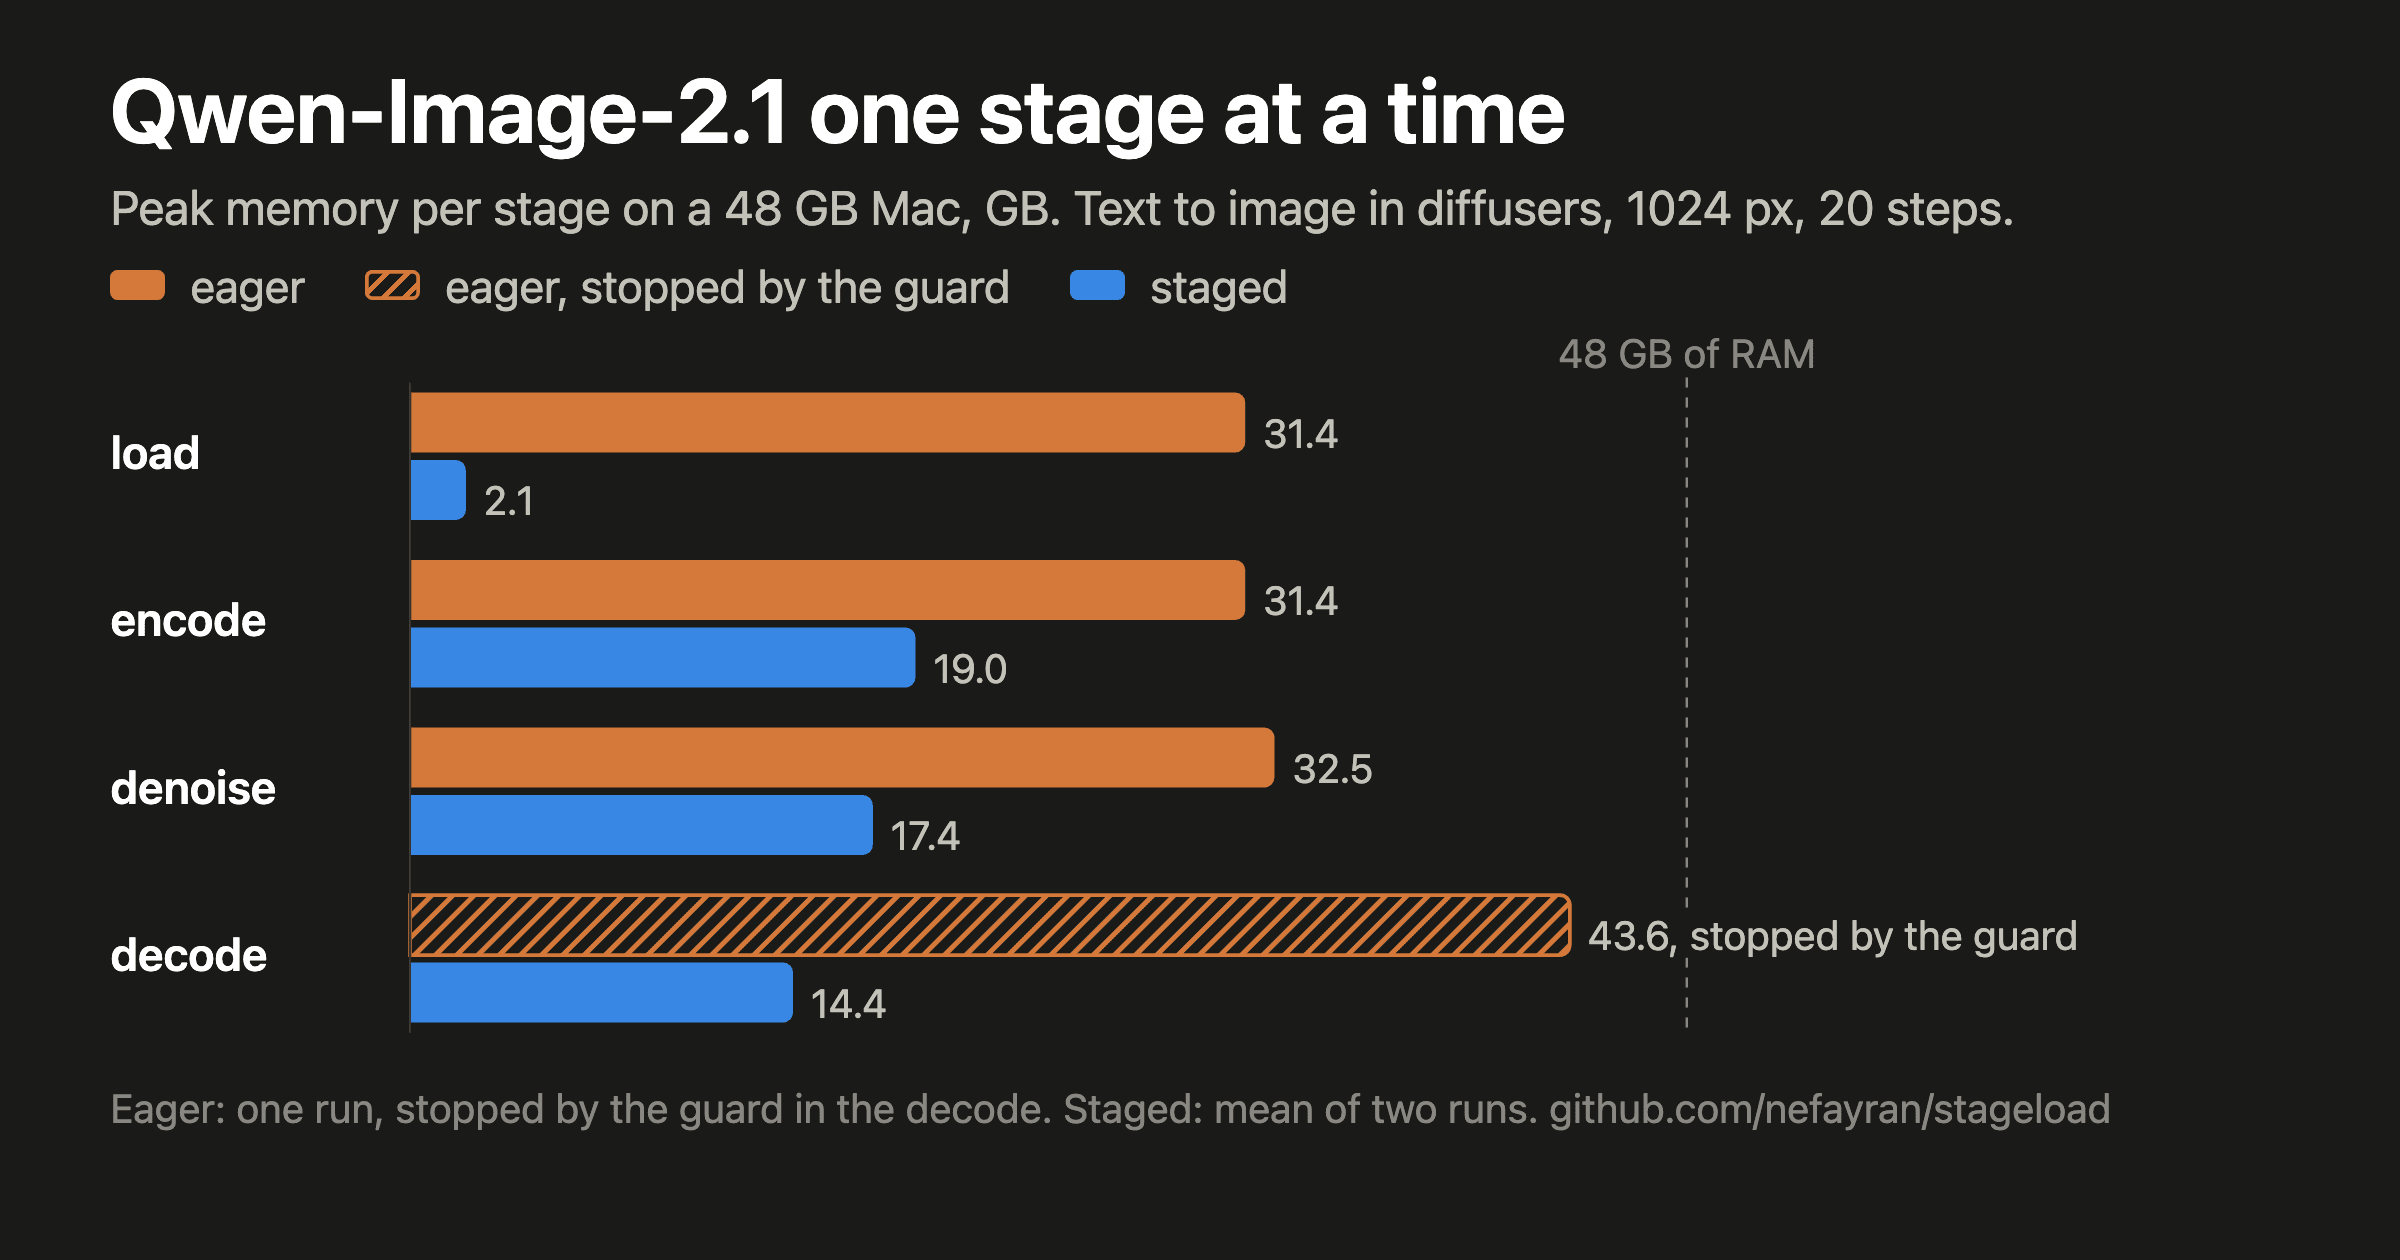
Qwen-Image-2.1 one stage at a time: a second pipeline for stageload
A text-to-image pipeline in diffusers, loaded with stageload on a 48 GB Mac: eager reached 43.6 GB in the VAE decode and the memory guard stopped it, while staged stayed at 19.0 GB or less with the pipeline's code unchanged.
Read the note →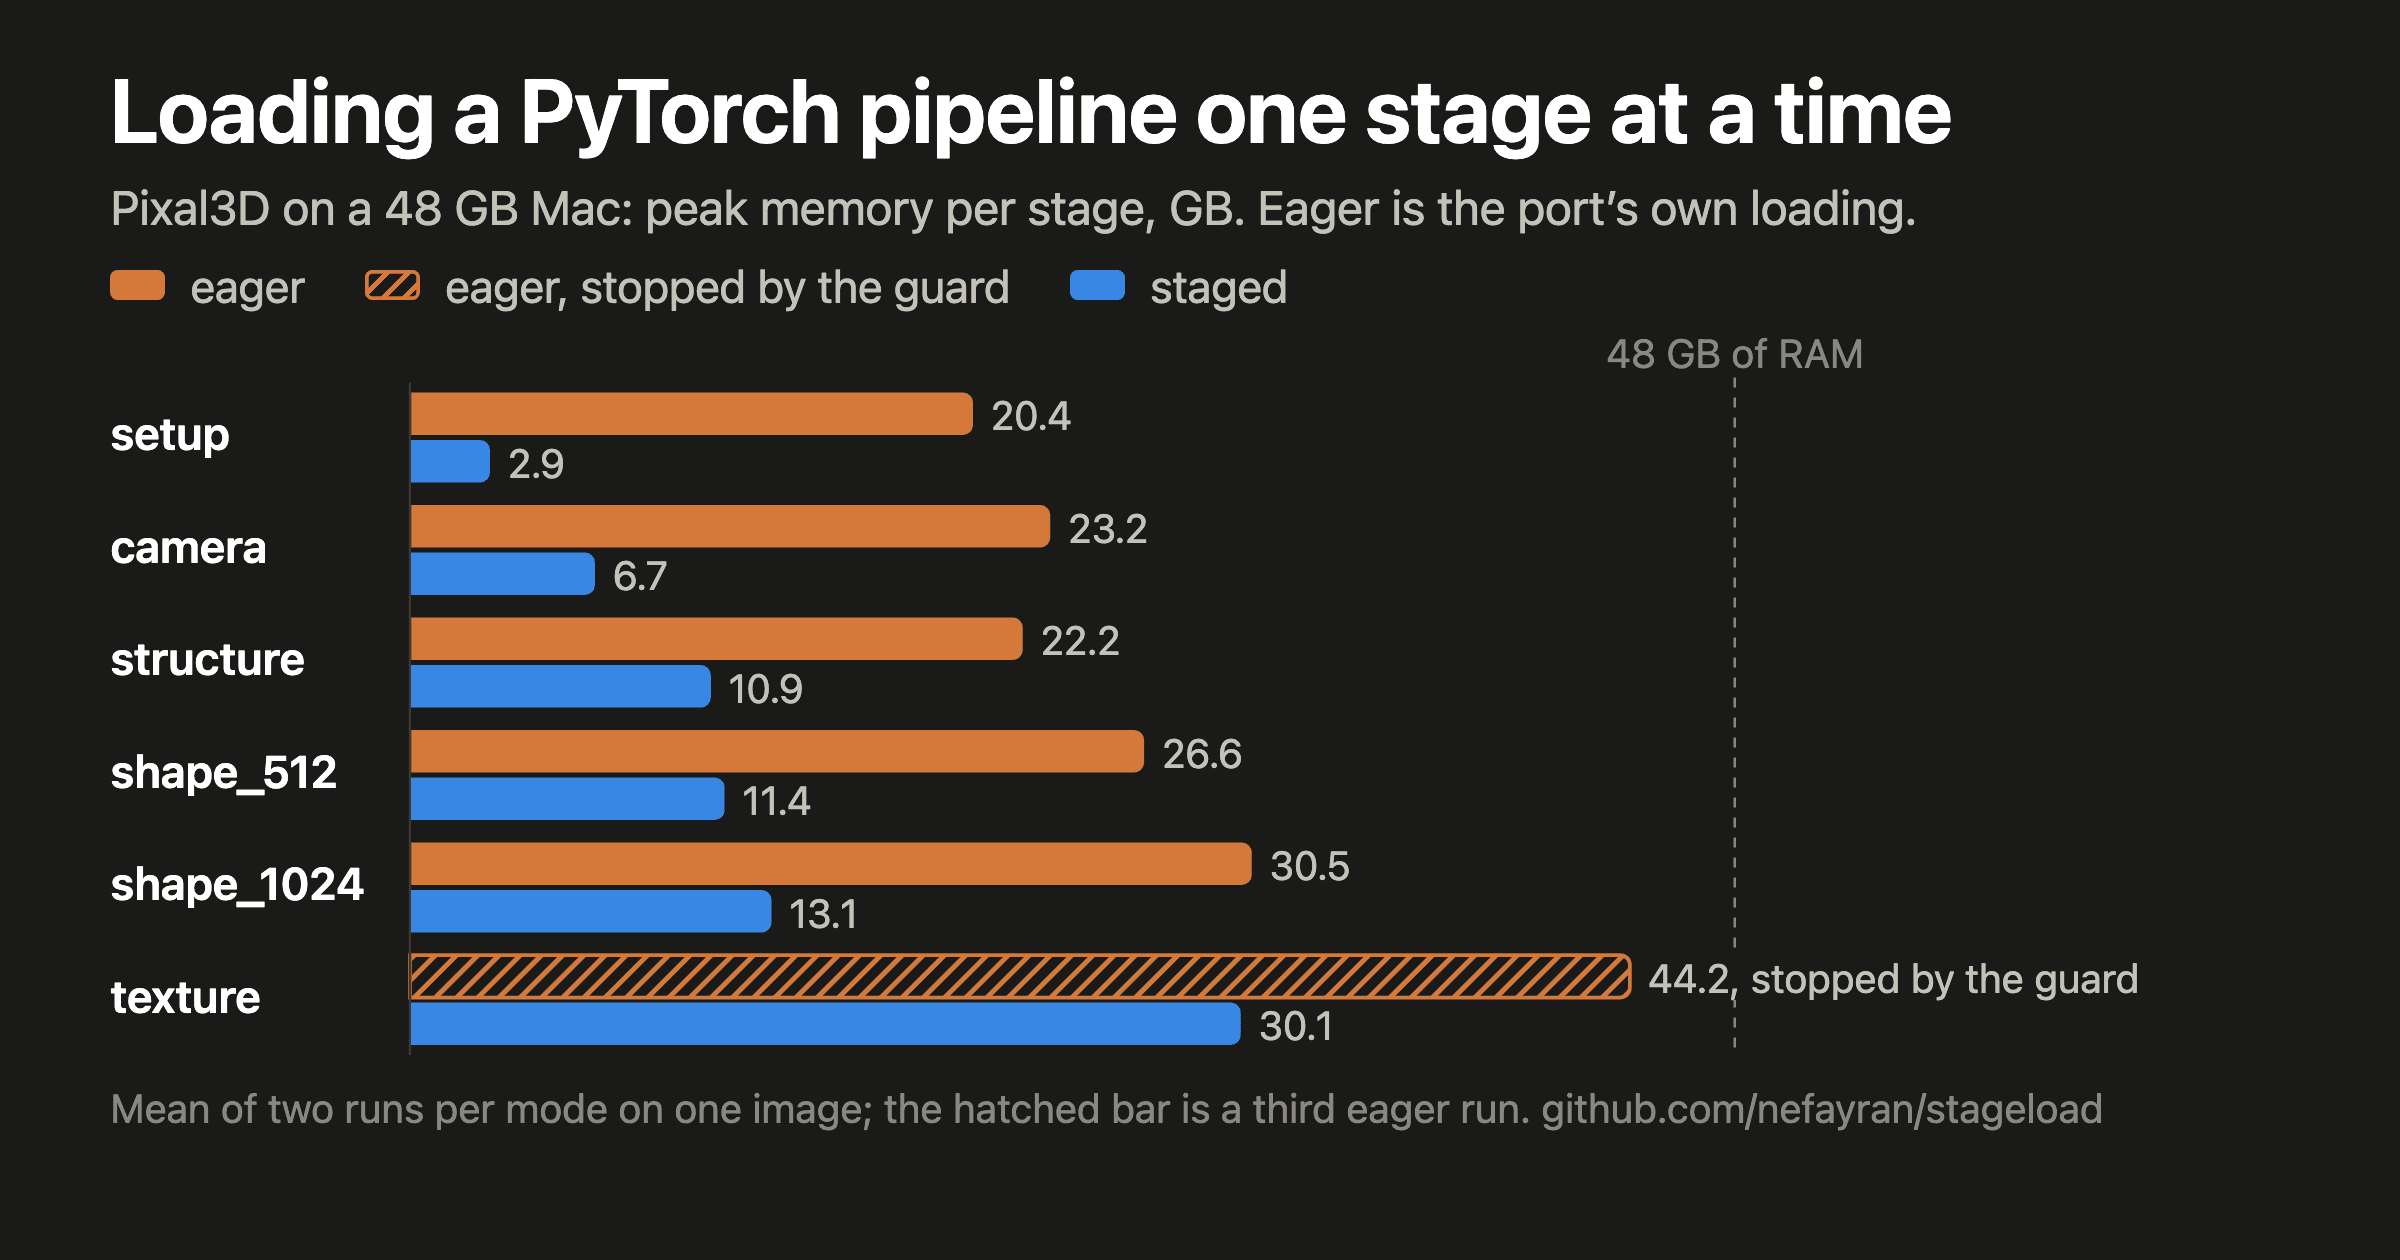
Loading a PyTorch pipeline one stage at a time: Pixal3D on a 48 GB Mac
stageload loads the models a stage needs when the stage begins and releases them when it ends, for any PyTorch pipeline that runs its models in turn. On Pixal3D-mac on a 48 GB Mac it cut the peak by 11 to 17 GB in every stage both versions reached, where the port's own loading pushed the machine into swap until a guard stopped it.
Read the note →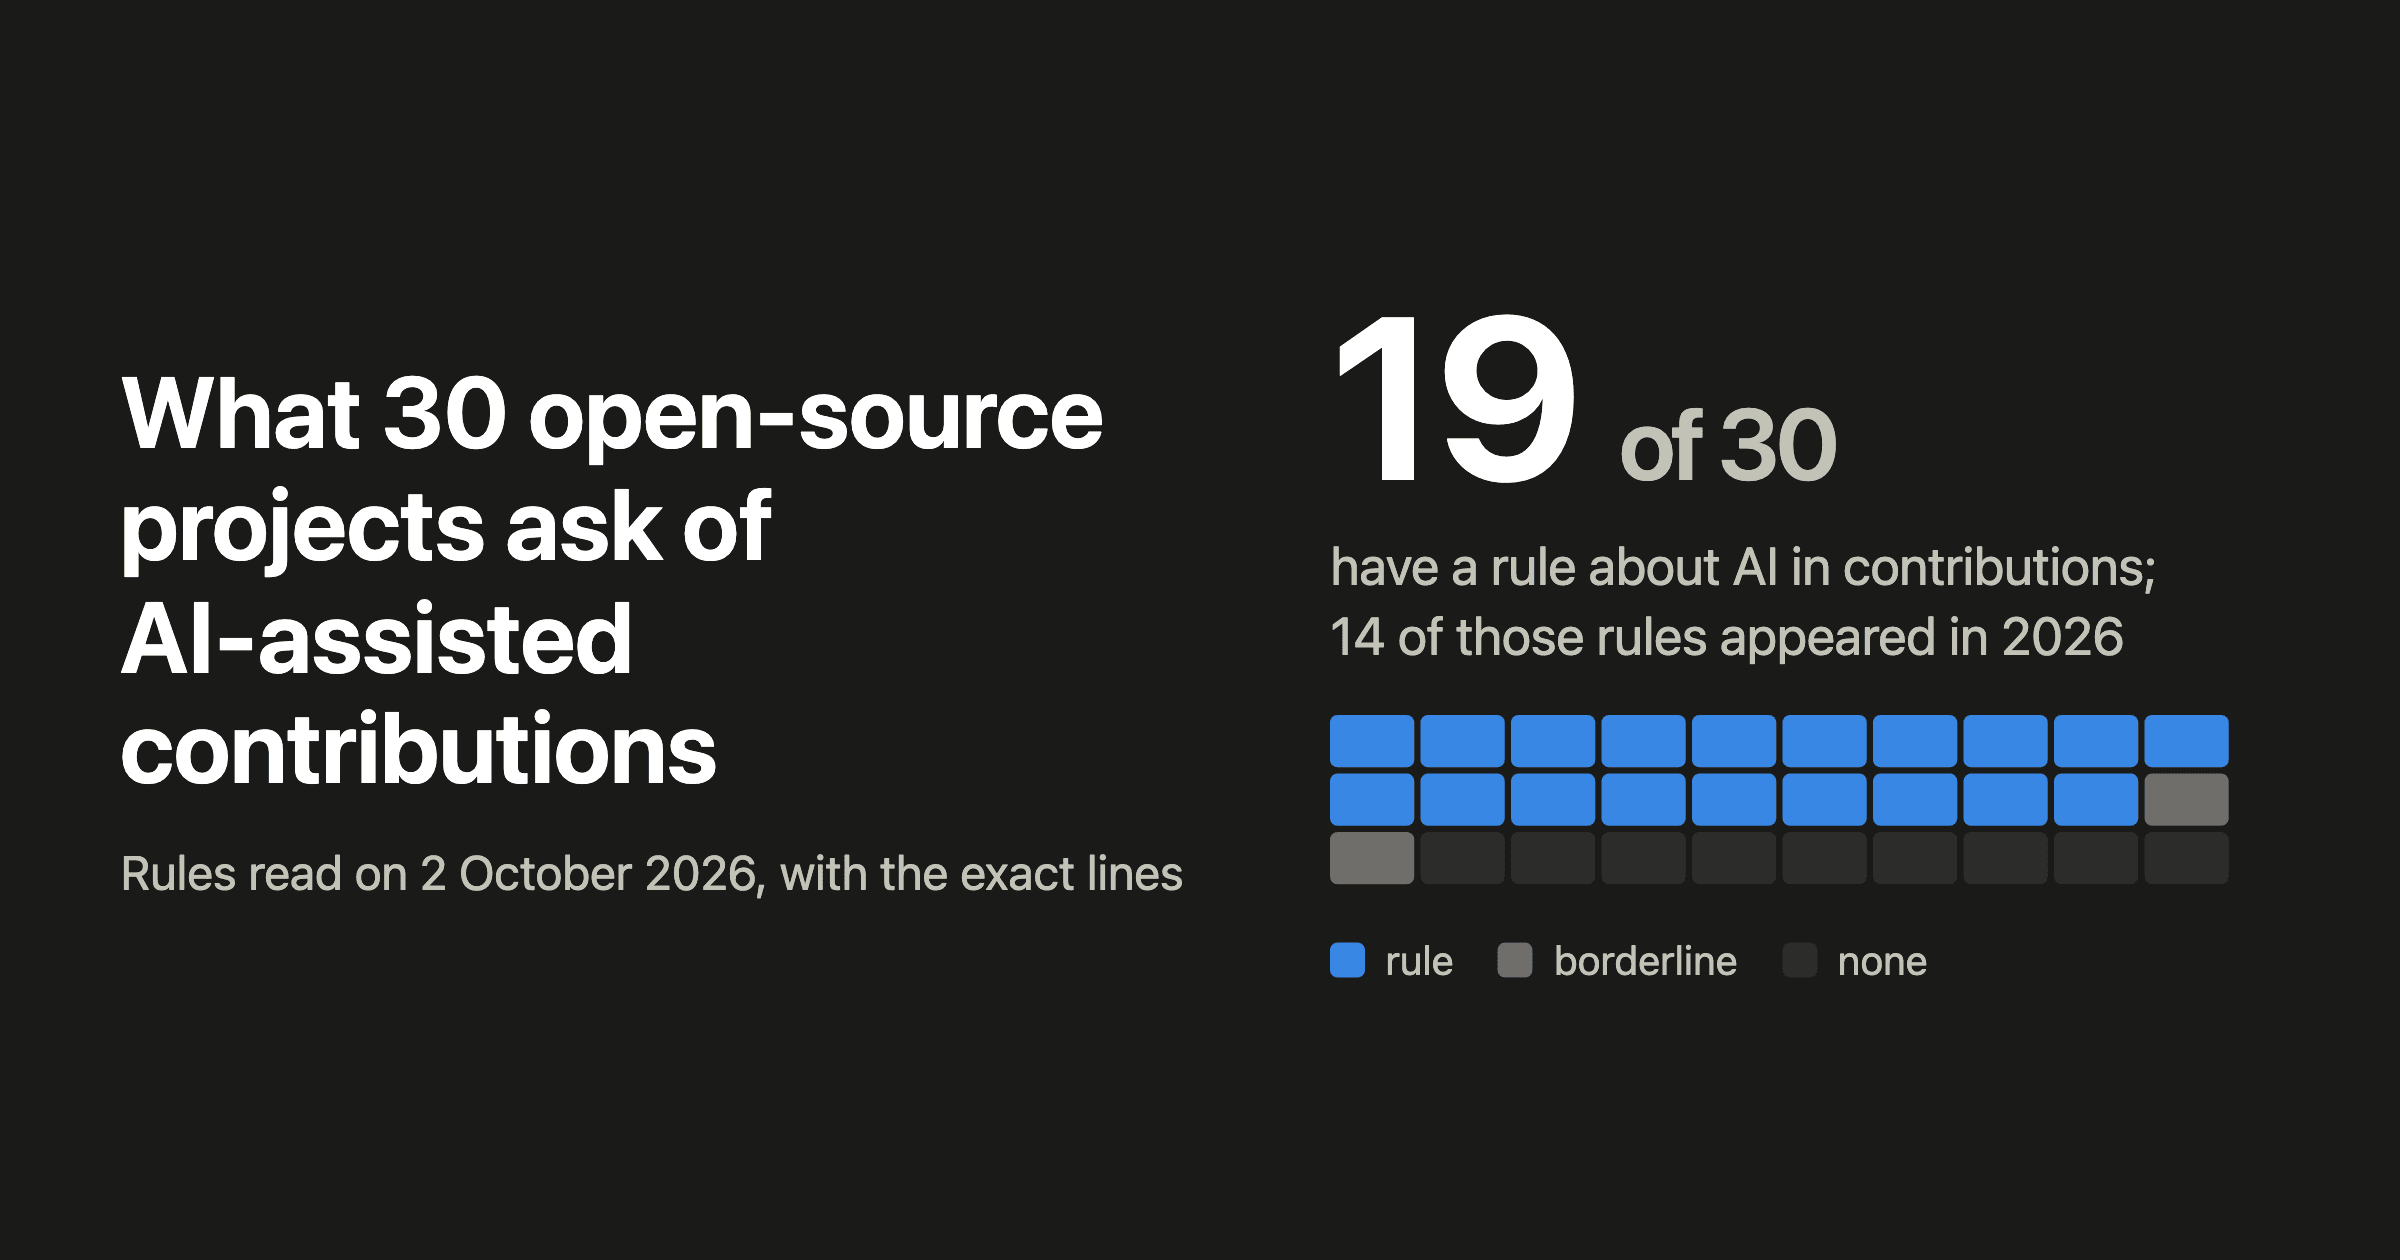
What 30 open-source projects ask of AI-assisted contributions
On 2 October 2026 I read the contribution rules of 30 open-source repositories. 19 have a rule about AI, and 14 of those rules appeared in 2026. Fifteen ask you to say that you used AI, ten want a person to write the text, and the commit trailer that coding agents add by default is required by some and banned by others. Then what happened to the agent-assisted work I sent to twelve projects that week.
Read the note →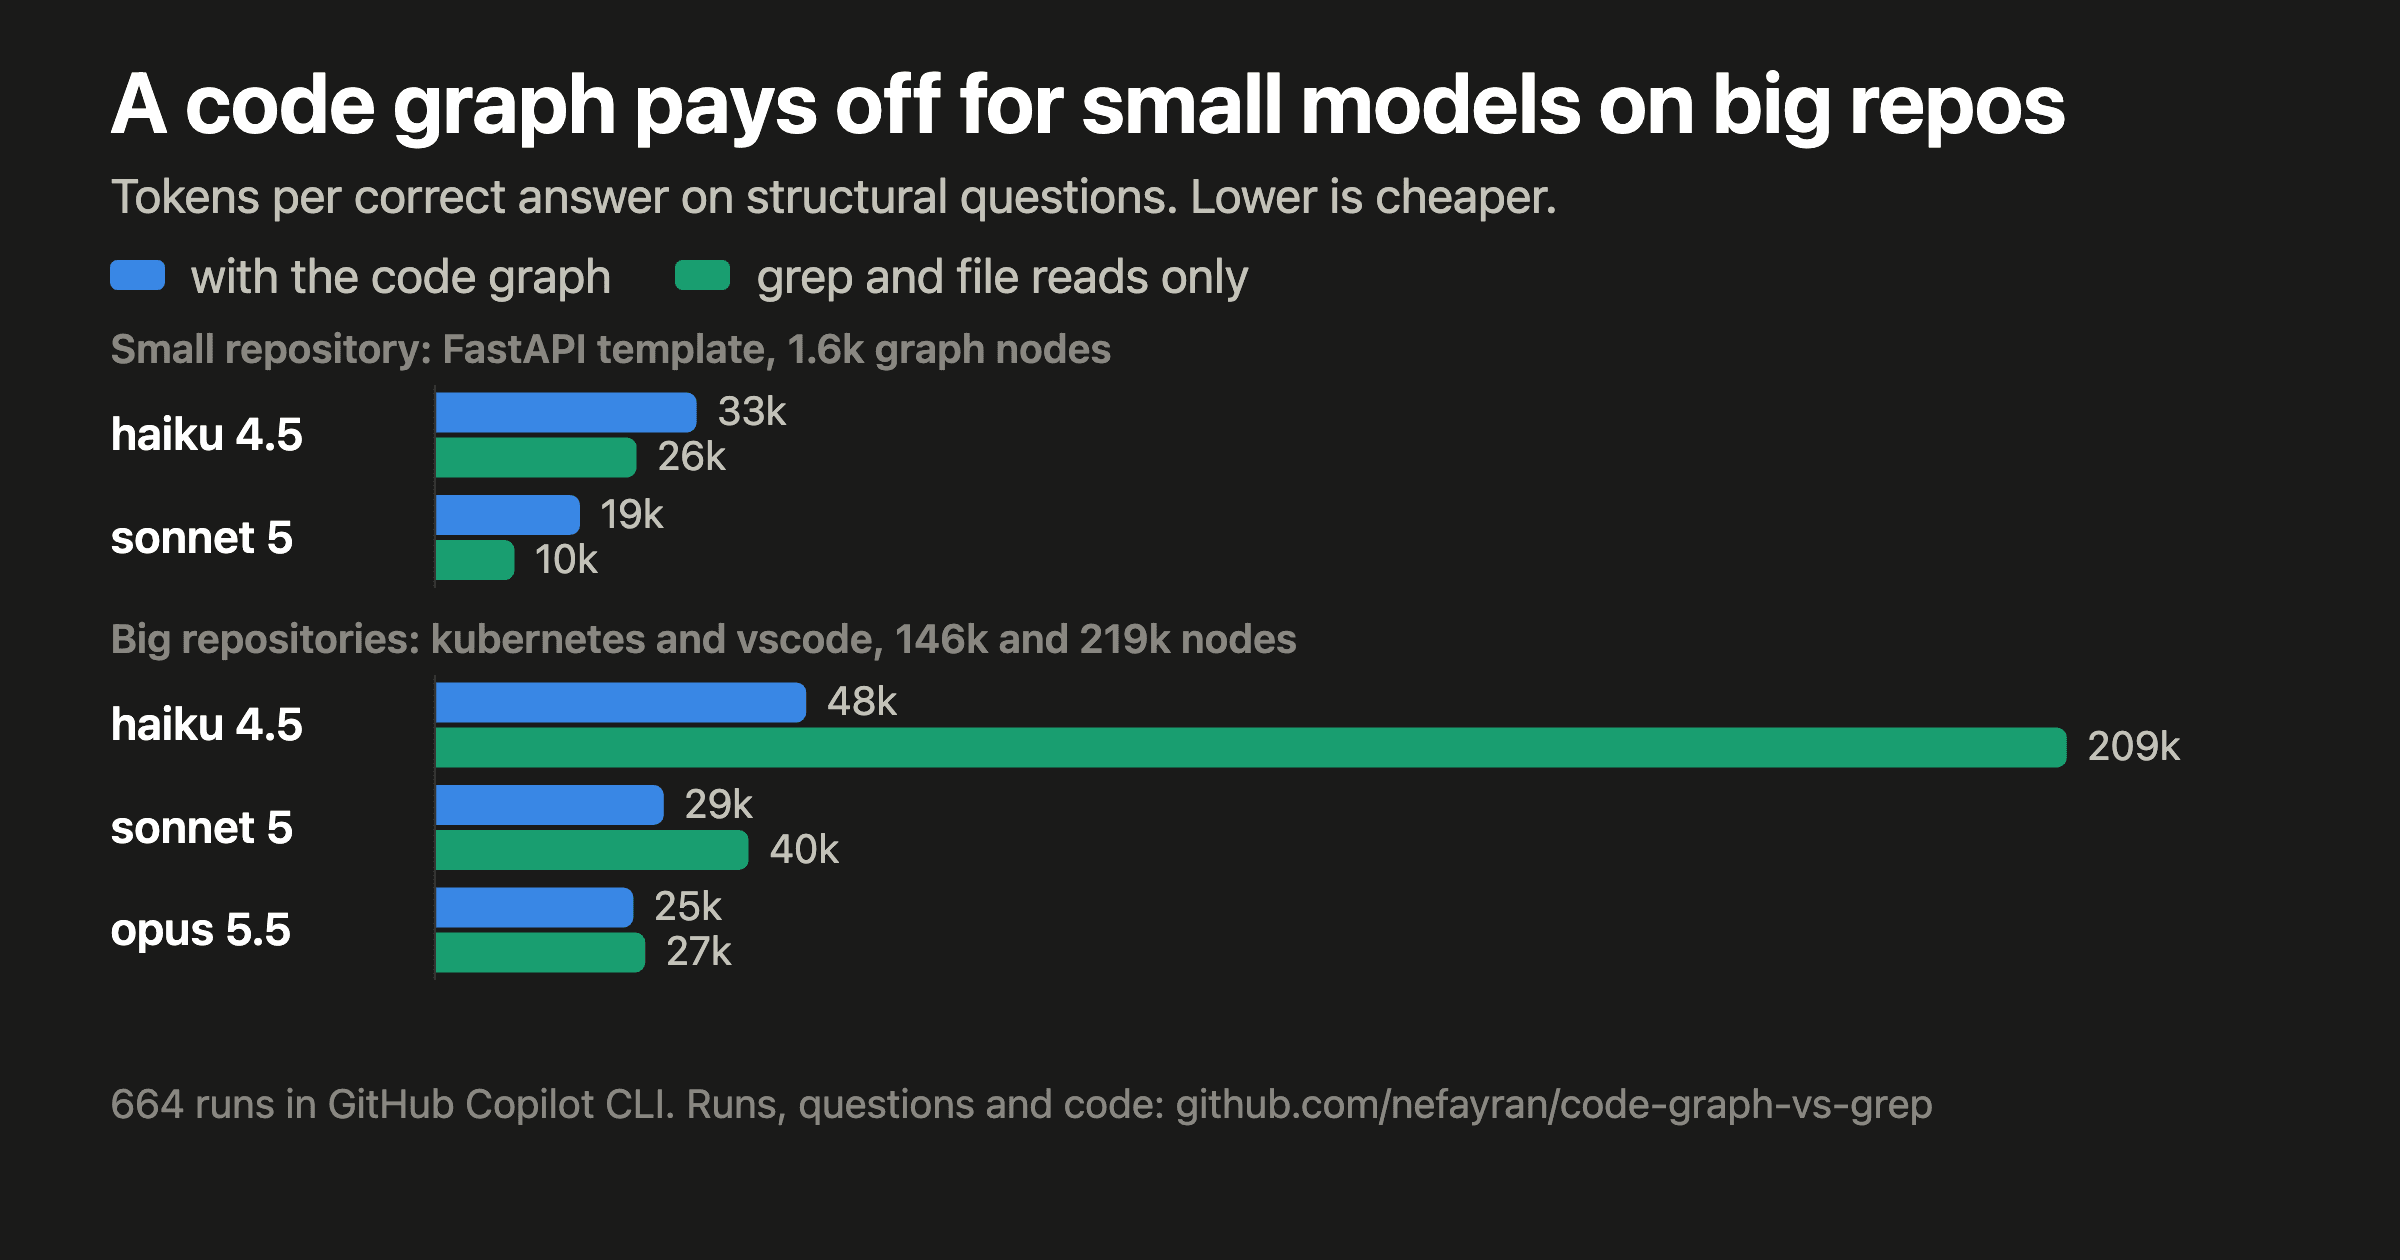
Where a code graph pays off: big repositories, small models
664 headless runs in GitHub Copilot CLI on four public repositories from 1.6k to 219k graph nodes, with haiku 4.5, sonnet 5 and opus 5.5. On kubernetes and vscode a code graph cut haiku's cost on structural questions to 0.29 of grep's. Sonnet saved about a quarter, opus nothing, and on a small repository the graph cost sonnet 40 to 50% more.
Read the note →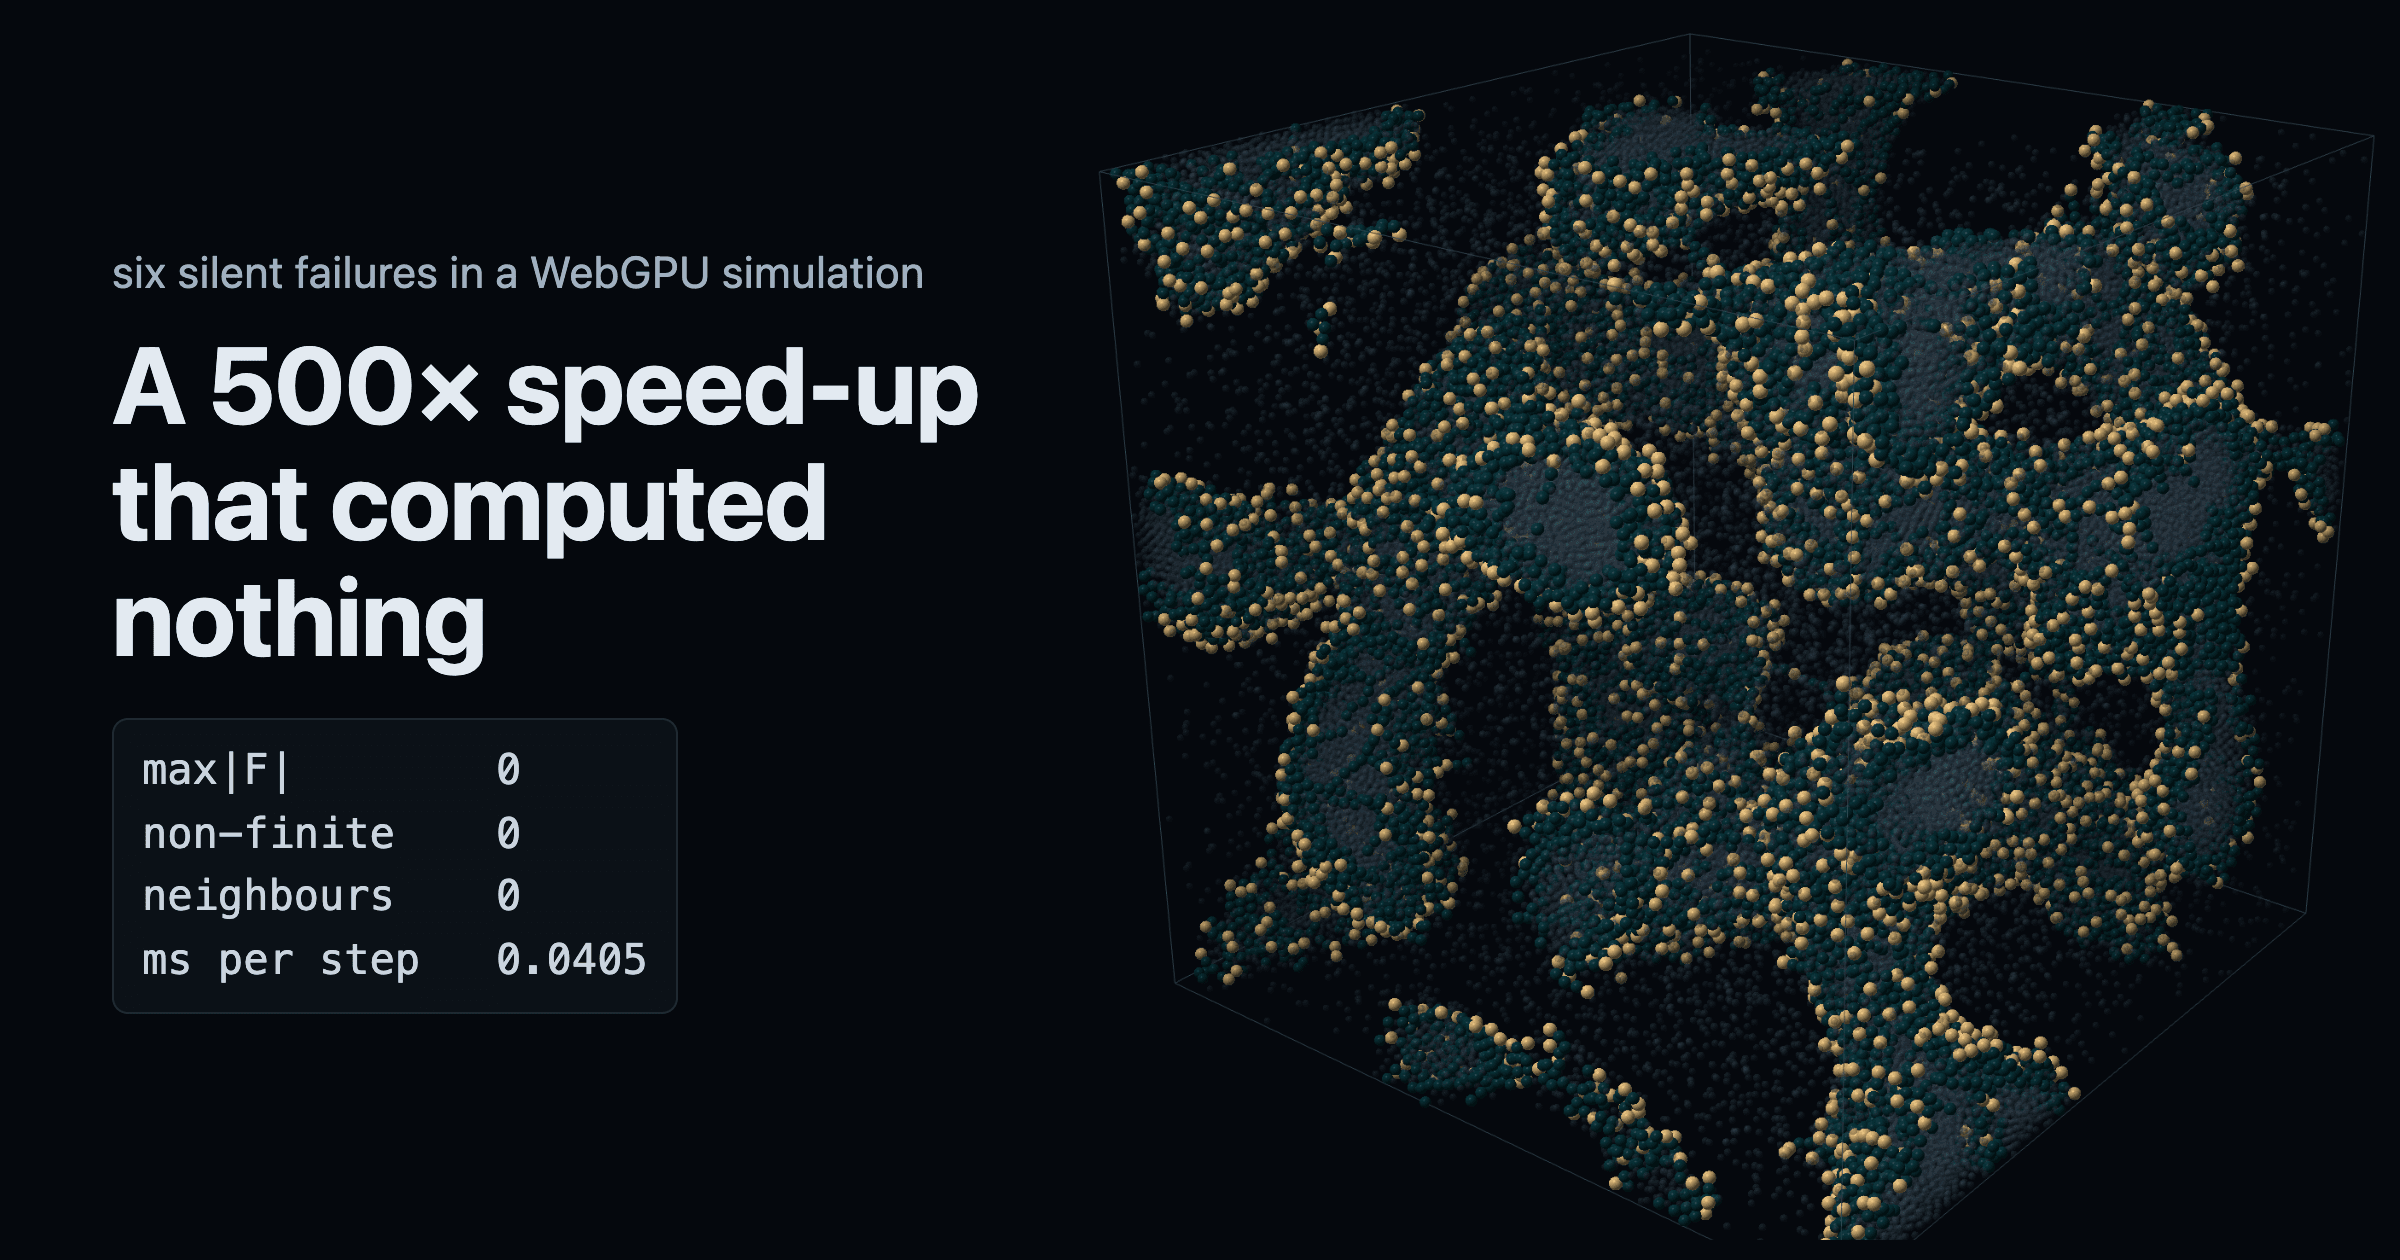
A 500× speed-up that computed nothing: six silent failures in a WebGPU simulation
Six bugs in a WebGPU particle simulation raised no error and returned believable numbers. What each one looked like and what changed.
Read the note →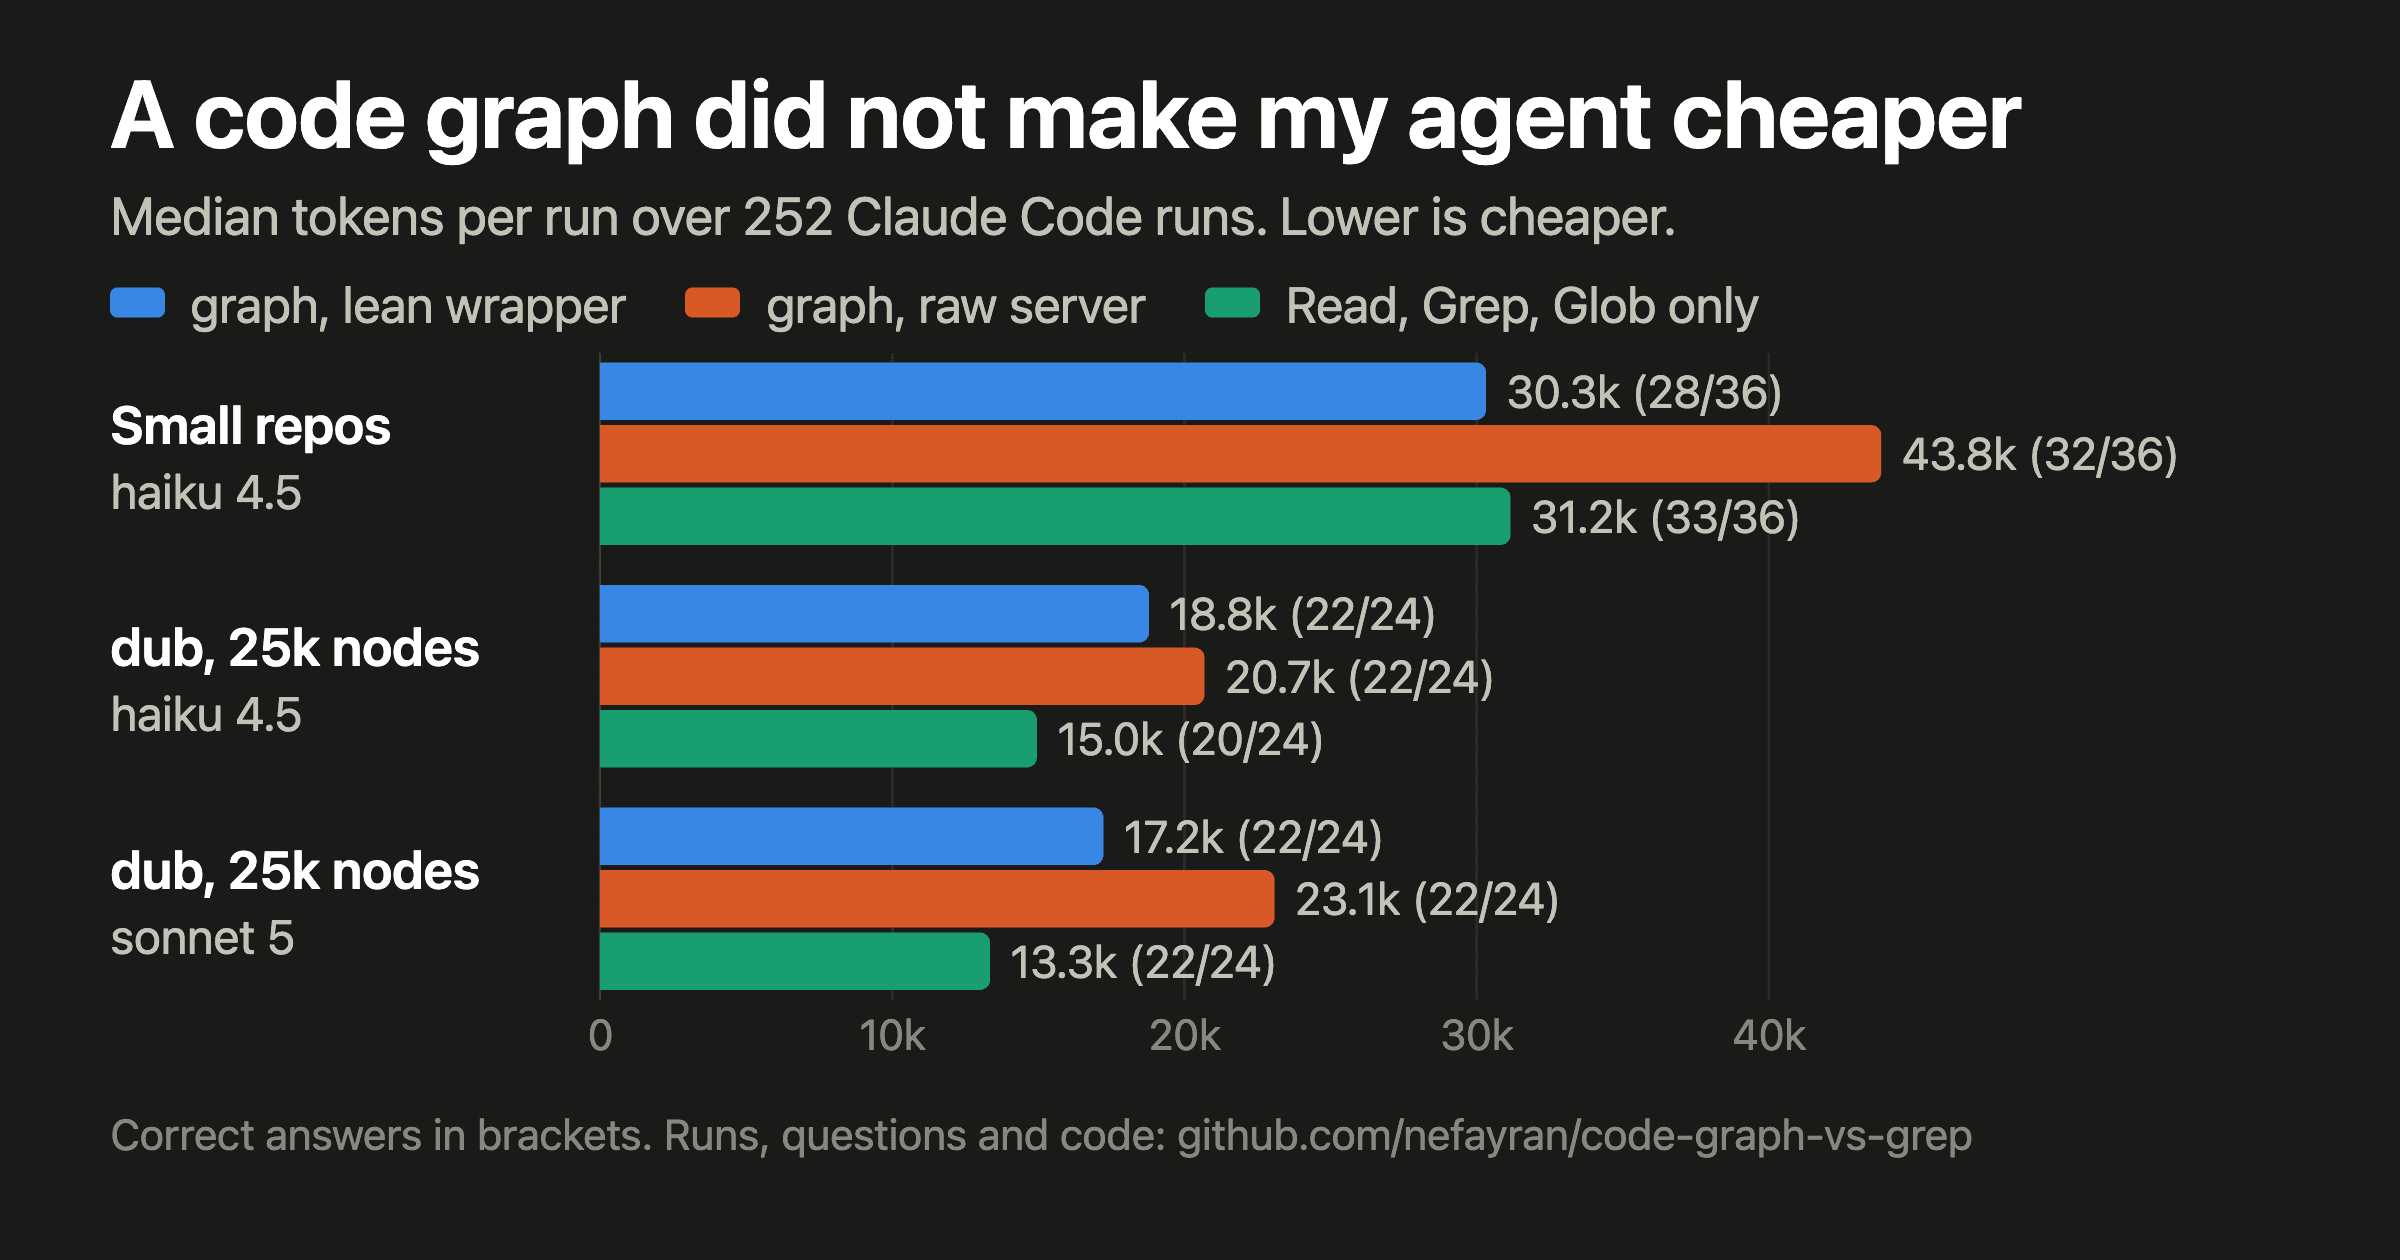
A code graph did not make my coding agent cheaper
252 headless Claude Code runs on public repositories, from 1.6k to 25k graph nodes, with haiku 4.5 and sonnet 5. The graph never beat Read and Grep on tokens, a lean wrapper always beat the raw graph server, and with default settings the agent barely called the graph.
Read the note →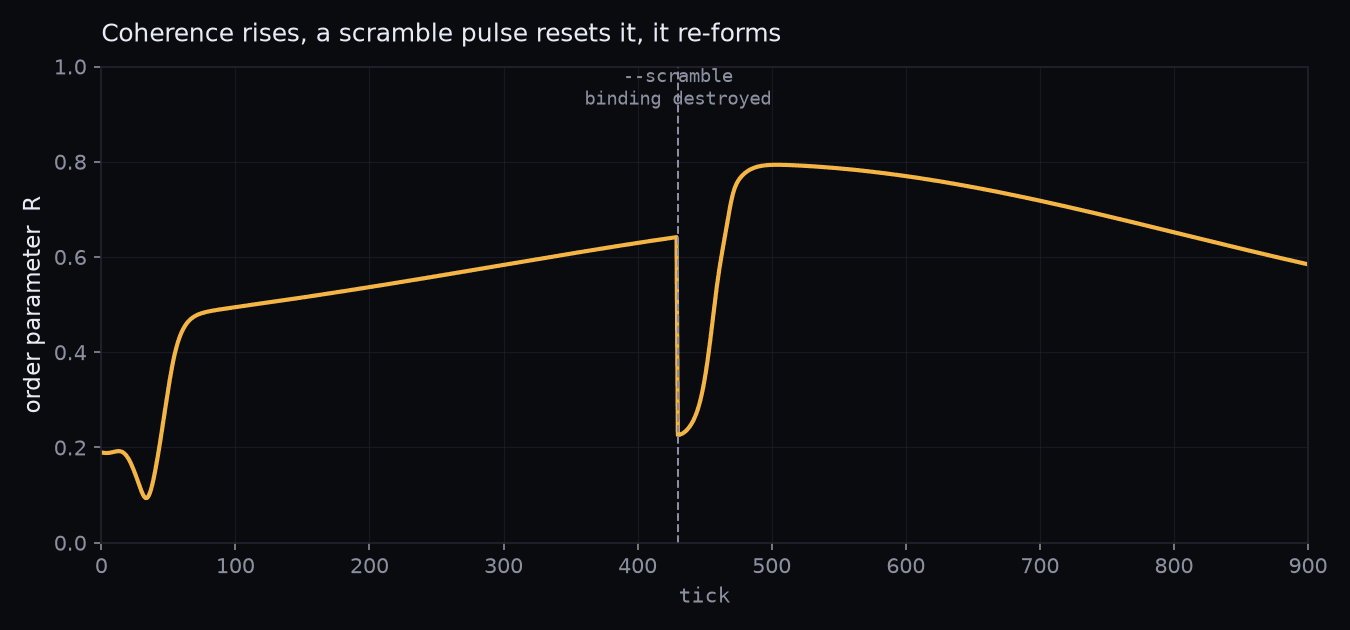
Oscillators, Embeddings, and the Control That Caught Us Lying
Experiment 002 replaced the language nodes with concept-neurons that fire in phase, coupled by embedding similarity. A control that scrambled the phases still got a coherent reading, so the meaning came from the model reading the field, not from the network.
Read the note →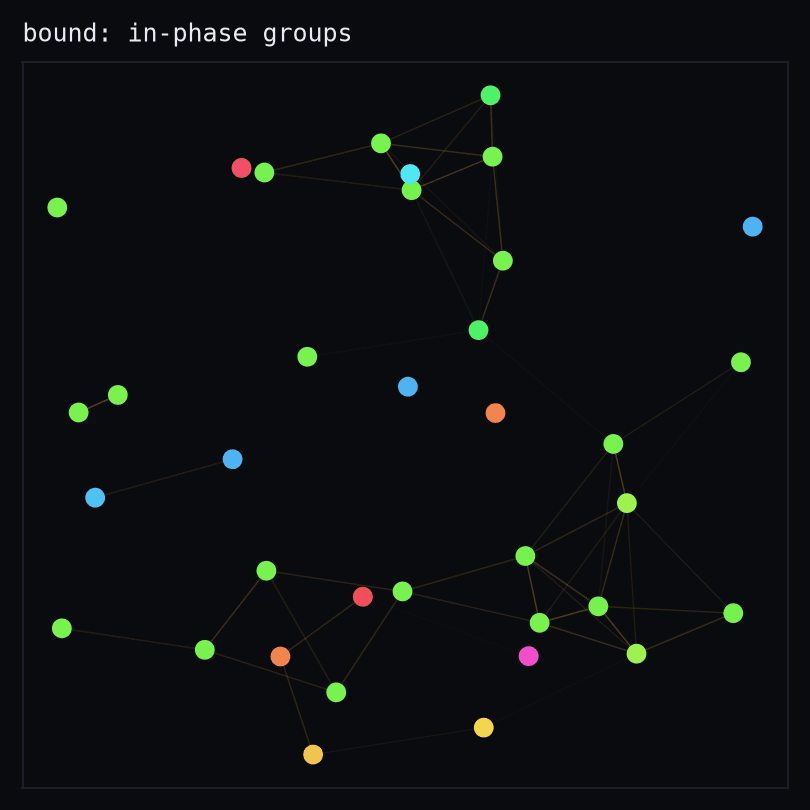
We Wired Language Models Into a Mind. It Collapsed Into One Sentence.
Eight copies of one language model on a ring, with no roles, were told to continue each other's thought. They converged on a single sentence and kept repeating it: mode collapse. A negative result.
Read the note →