The second stageload note ran Qwen-Image-2.1 on a 48 GB Mac two ways. The memory guard stopped eager loading in the VAE decode, and staged loading finished. diffusers has a third way built in, enable_model_cpu_offload, which keeps each model on the CPU and moves it to the GPU only while it runs. On 8 October I ran it once, with the same prompt, size, steps, seed and guard limits as the runs of 6 October.
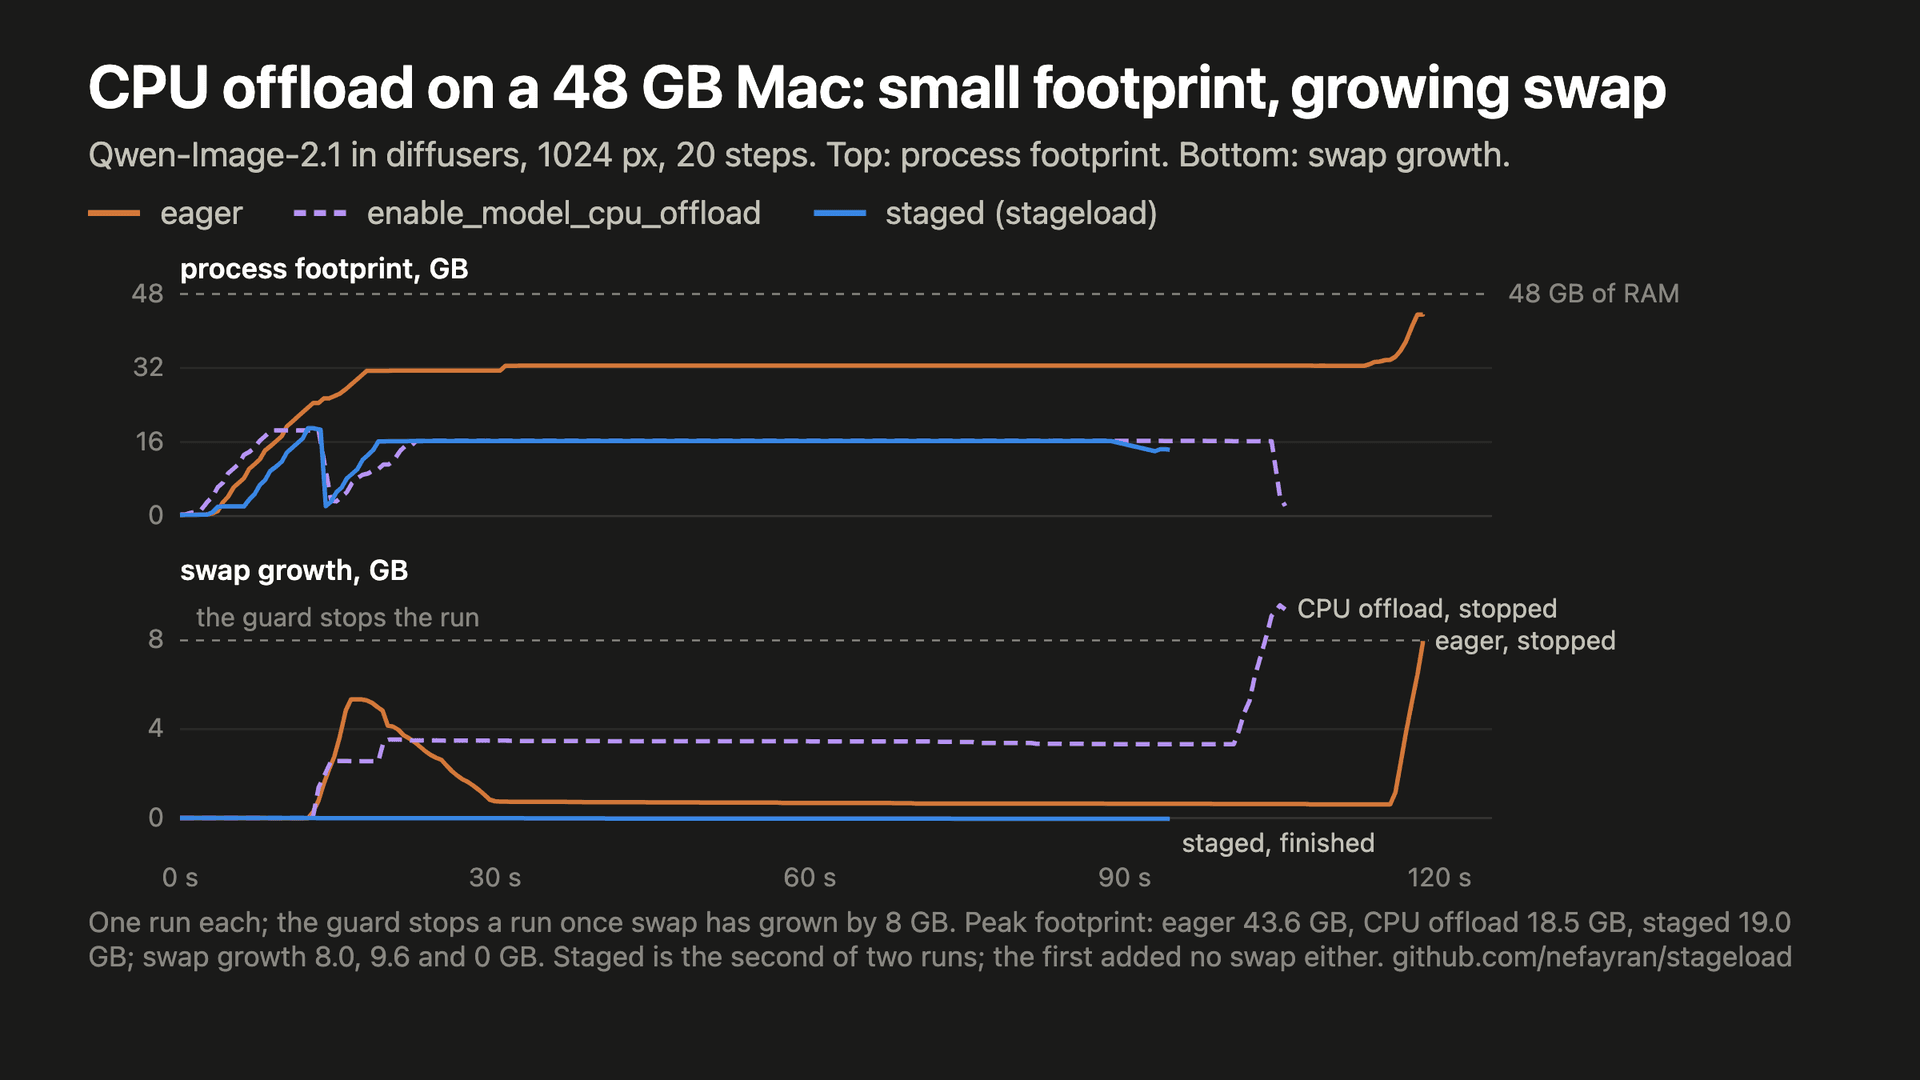
By the process footprint, offload looked like staged: it peaked at 18.5 GB, staged at 19.0 GB. Swap tells them apart. Encoding took 8 s and added no swap. During the 87 s of denoising, swap grew by 3.5 GB and available memory fell to 27 %. The VAE decode took swap growth to 9.6 GB and available memory down to 22 %, and the guard stopped the run 105 s in, before it wrote an image. Staged added no swap in either of its two runs and finished in 94 and 124 s.
The footprint cannot show this, because it does not count pages that are already in swap. On a Mac the CPU and the GPU share one pool of memory, so a model kept "on the CPU" sits in the same RAM as the model that is running. Judged by footprint alone, offload would sit next to staged. Judged by swap, it sits next to eager, which the guard stopped at the same point after 8 GB of new swap.
What I could not show
This is one run. A second would have pushed the machine into swap again for an outcome the guard had already decided. I did not measure which pages went to swap, and I did not try offload on a Mac with more memory.
The script is bench/qwen_image_offload.py, and the trace is in the repository. stageload installs with pip install stageload.